Convergent validity is a subtype of construct validity — whether a test or measure captures the psychological concept it claims to assess. It evaluates the extent to which responses on a test or instrument exhibit a strong relationship with responses on conceptually similar tests or instruments. Not only should a construct correlate with related variables, but it should not correlate with dissimilar and unrelated ones.
Key Takeaways
- Definition: Convergent validity is the degree to which two measures of related constructs are, in fact, related.
- Methods: These can be different methods (e.g., self-report questionnaires and behavioral observations) or different instruments measuring the same construct.
- Threshold: High positive correlations, generally above 0.5, between measures of the same construct indicate convergent validity.
- Discriminant Validity: Convergent validity is often assessed alongside discriminant validity, which checks that measures of unrelated constructs are indeed not related.
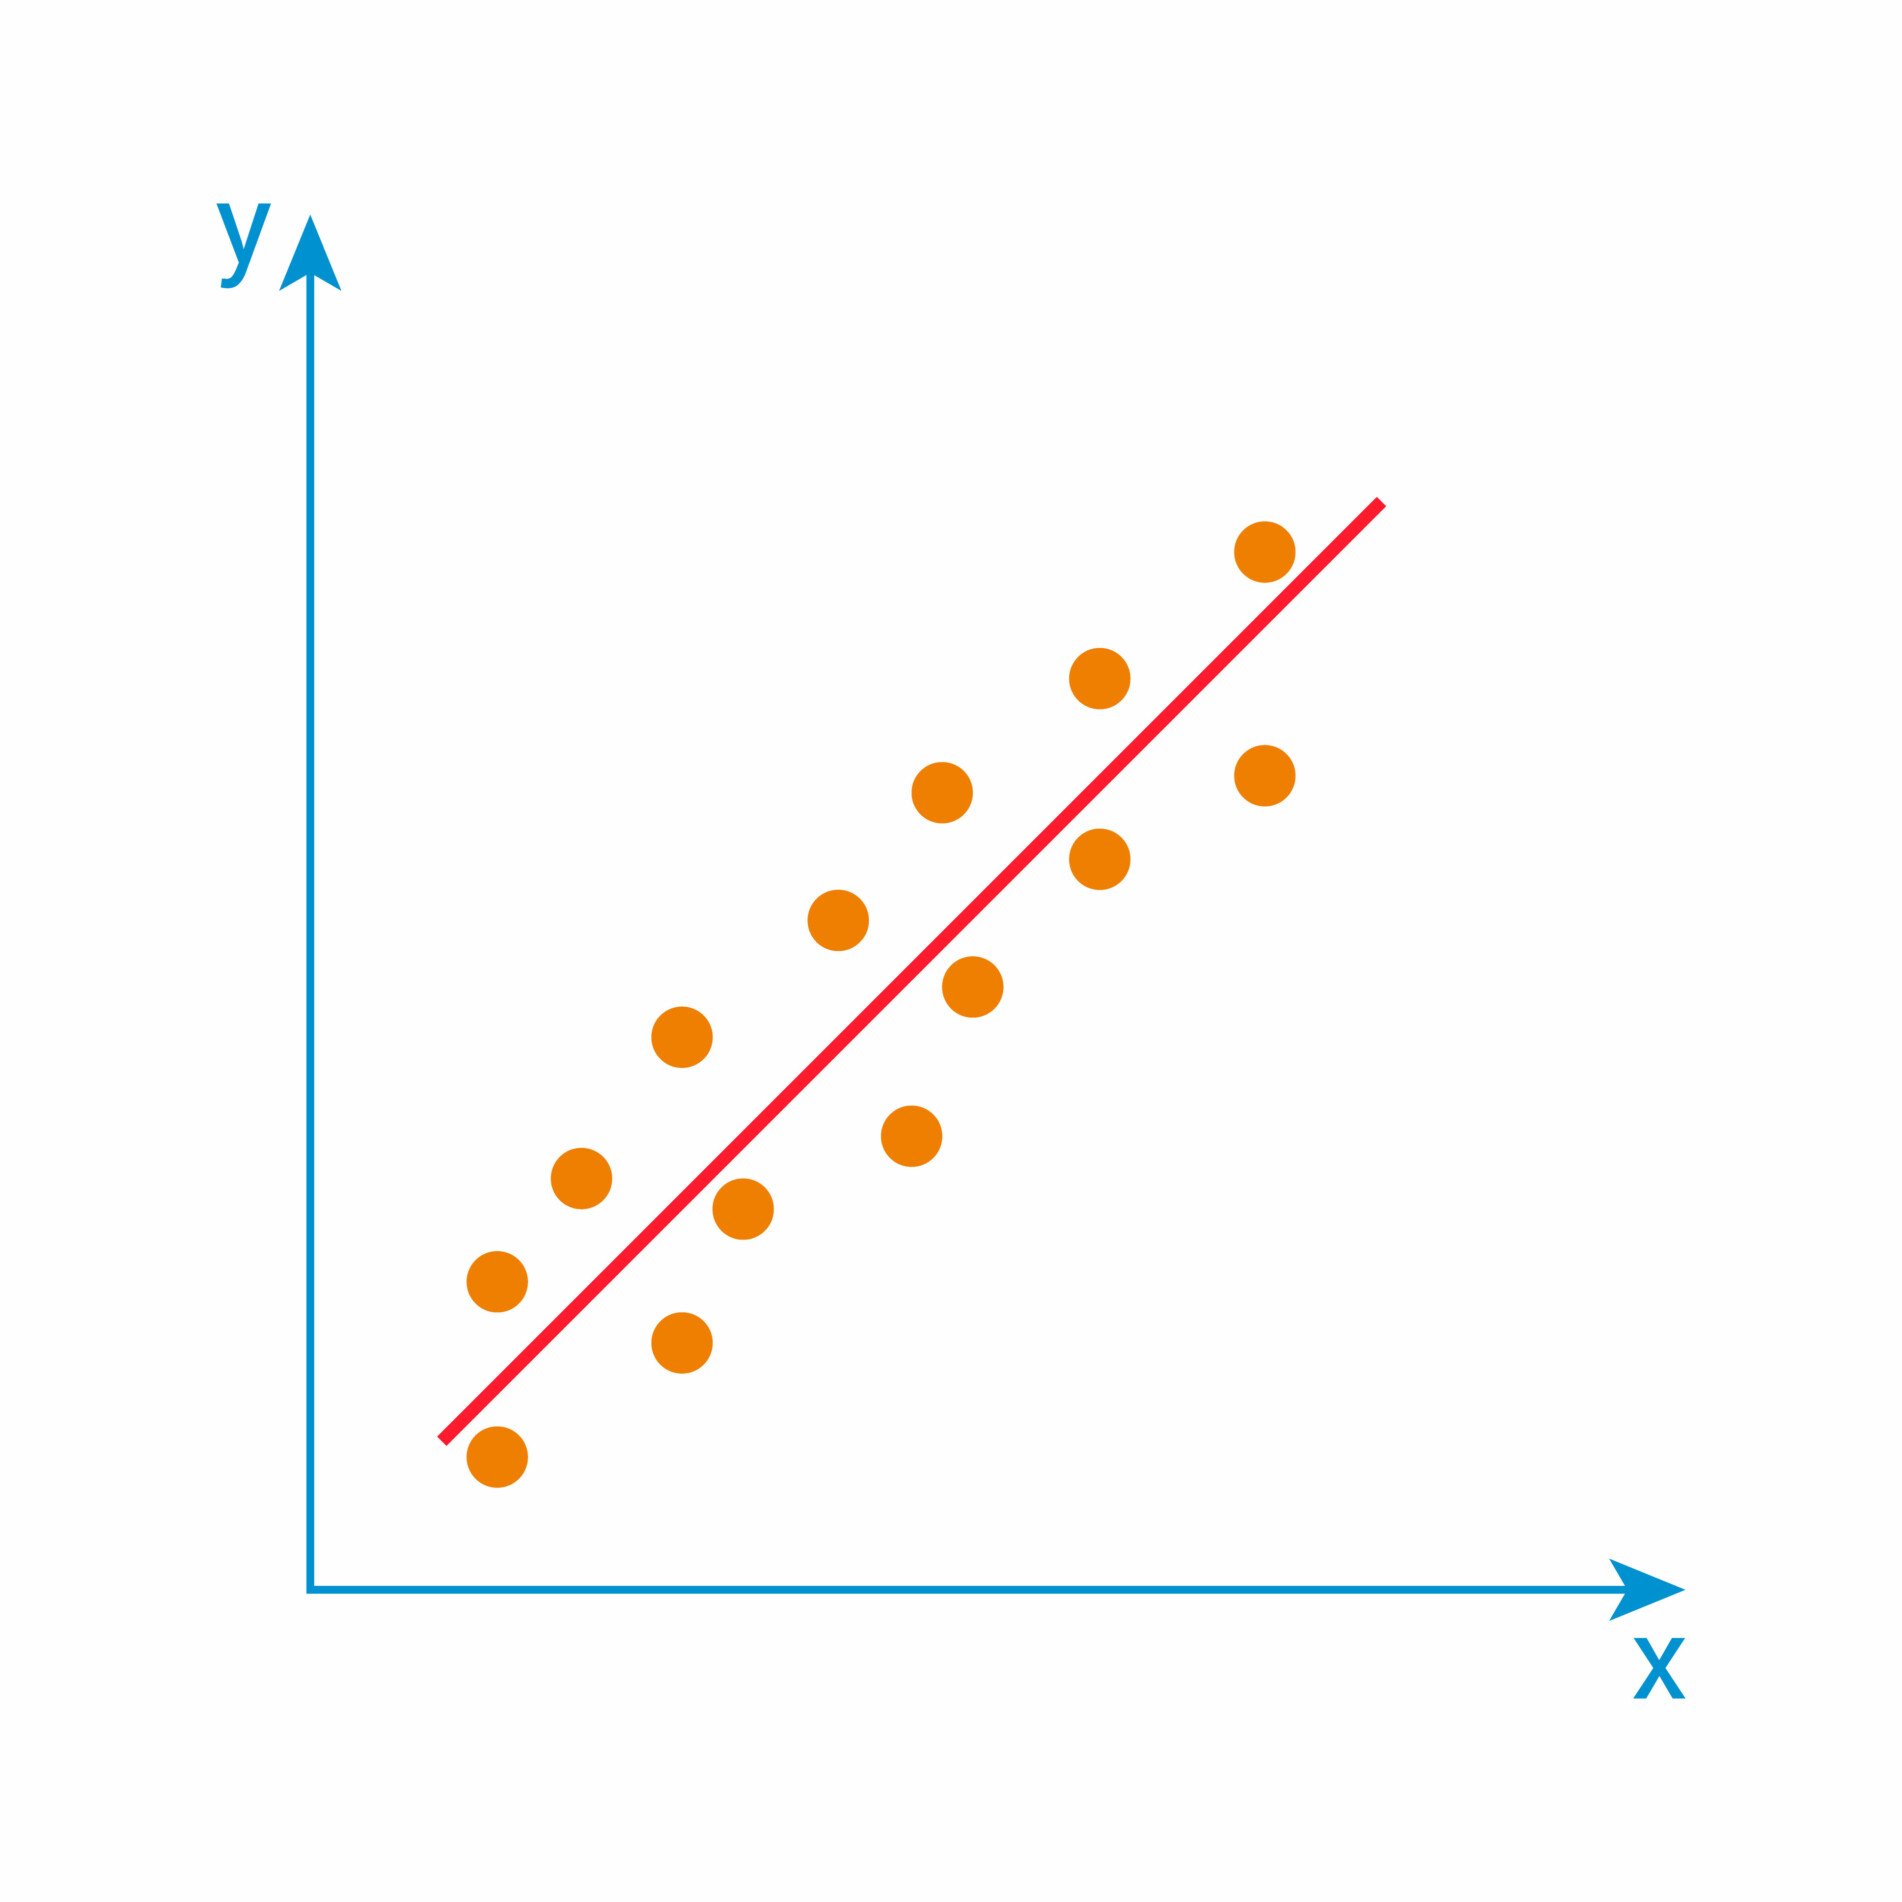
Examples of Convergent Validity
Depression Questionnaires
If a psychologist is attempting to measure depression among a population using two different tests, they can examine how closely related the responses from those tests are to one another.
If the results from both tests correlate strongly, convergent validity has been established. If there is no significant correlation between test results, the lack of correspondence needs further investigation (Krefetz et al., 2002).
IQ Tests
Researchers establish the concurrent validity of IQ tests by comparing the IQ test scores with other measures that assess related mental abilities.
Take an IQ test, then a test of verbal skills. Researchers can compare the two scores to see whether they correlate.
Firmin et al. (2008) did this with IQ tests. They evaluated concurrent validity by correlating scores on an established IQ test, the Composite Intelligence Index, with scores from their own web-administered tests.
This type of comparison helps to show that the IQ test is measuring what it purports to measure – intelligence, thus helping to establish construct validity.
Measuring Extroversion
Imagine a study designed to assess extroversion. The researchers use three different methods to collect data:
- A self-report questionnaire where participants rate their agreement with statements about sociability.
- Other-report ratings, in which the participants’ romantic partners describe their enjoyment of social events.
- Behavioral observation, with researchers observing how participants interact with strangers in a waiting room.
If these three methods yield scores that are highly correlated, it would be evidence for the convergent validity of the extroversion measures.
Measuring Mood: The PANAS
A widely used example comes from mood research. Watson, Clark and Tellegen (1988) developed the Positive and Negative Affect Schedule (PANAS), a brief self-report scale, and needed to show it agreed with existing, longer mood measures.
Aim: To test whether a short 20-item mood scale could show strong convergent validity with established longer mood measures, while keeping its two subscales appropriately independent of each other.
Method: The design was simple. Participants completed the 20-item PANAS alongside longer, established mood measures. The researchers then correlated the subscales with those measures, and with each other.
Results: Both PANAS subscales correlated strongly with the corresponding subscales of the longer, established measures. The correlation between Positive and Negative Affect was low.
Conclusion: A brief self-report scale can be both convergently valid, by agreeing with longer established measures, and discriminantly valid, by keeping its own subscales appropriately independent.
One caveat applies. Both the PANAS and its comparison measures are self-report, so part of the correlation could reflect a shared method, not just a shared construct. This limitation is discussed further under Critical Evaluation below.
How to measure convergent validity
Convergent validity is a matter of degree, not an all-or-none phenomenon. Convergent validity is also not a one-time determination.
Rather, it is an ongoing process that should be continually reevaluated as new information becomes available
Convergent validity can be measured using several statistical methods. The most common approaches are:
Correlation coefficients
The most common method for assessing convergent validity is calculating the correlation coefficient between scores from different measures hypothesized to assess the same construct.
To establish convergent validity, researchers typically set a threshold for the correlation coefficients or factor loadings.
The exact threshold may vary depending on the field and the nature of the constructs being measured, but values above 0.5 are generally considered acceptable.
Pearson’s correlation coefficient (r) is one option. It applies when both measures are continuous and normally distributed.
Spearman’s rank correlation coefficient (ρ) is used when the measures are ordinal or when the assumptions of Pearson’s correlation are not met.
While a high correlation is a positive indicator, it’s crucial to remember that it doesn’t guarantee the measures are accurately assessing the intended construct.
It’s possible they could be measuring a different, shared construct.
Factor analysis
Exploratory Factor Analysis (EFA) can be used to identify the underlying factor structure of a set of measures.
Confirmatory Factor Analysis (CFA) can be used to test whether the measures load onto the expected factors based on theory.
High factor loadings (generally above 0.5) of the measures on the same factor suggest convergent validity.
Structural Equation Modeling (SEM)
SEM is a more advanced technique that combines factor analysis and regression analysis.
It allows for the simultaneous assessment of convergent validity, discriminant validity, and other types of validity.
High factor loadings and low cross-loadings in SEM support convergent validity.
Multitrait-Multimethod Matrix (MTMM)
MTMM is a method that assesses both convergent and discriminant validity by examining the correlations between different traits (constructs) measured by different methods.
Convergent validity is assessed by examining the strength of correlations between the same trait measured by different methods (monotrait-heteromethod correlations).
Convergent validity is supported when the correlations between measures of the same trait using different methods are high.
Discriminant validity uses two other kinds of correlation instead. It compares different traits measured by the same method (heterotrait-monomethod correlations) and by different methods (heterotrait-heteromethod correlations).
These correlations are expected to be weaker than the monotrait-heteromethod correlations.
Convergent validity is only one piece of the validation puzzle. Researchers also weigh content validity, criterion validity, and discriminant validity to build a full picture of a measure’s psychometric properties.
Critical Evaluation
Convergent validity evidence has real limits.
Two issues matter most: how much a single correlation can be trusted as evidence of a shared construct, and how consistently researchers actually check for it before publishing.
Shared-Method Variance and the Reliability Ceiling
Convergent validity is often established using two self-report scales, such as the PANAS. That method carries a hidden risk. Two self-report scales can correlate partly because they share a method, not just a construct. Mood, response style, and social desirability can all inflate the correlation.
That risk is manageable.
Researchers can address it by triangulating self-report evidence against non-self-report indicators. Behavioral, physiological, or informant-report measures help confirm the same construct outside a single method.
Reliability sets a hard limit too.
Spearman’s (1904) attenuation formula shows that the observed correlation between two measures can never exceed the square root of the product of their two reliabilities.
That ceiling is easy to forget.
An unreliable measure caps how strongly it can ever be shown to correlate with anything else. A striking convergent-validity result can reflect measurement noise as easily as genuine overlap, so reliability should be checked first.
Biology is no exception.
Elliott and colleagues (2020) found that many brain-imaging tasks used to measure psychological constructs had poor test-retest reliability, with an average reliability coefficient around .4. A measure this unreliable cannot support a strong convergent-validity claim, however sophisticated the technology behind it.
Contemporary Research
Two recent audits make the point directly.
Flake, Pek and Hehman (2017) audited how construct validity is actually reported in published social and personality research. They coded articles for whether each measure’s validity evidence was reported, and what kind — a full validation, a single prior use, or none.
The gap was stark.
Most measures had no validity evidence reported for the actual sample being studied. Researchers often just cited that a scale had been previously validated elsewhere, without re-checking it. When evidence was reported, it was often only internal-consistency reliability, not real convergent or discriminant evidence.
Hussey and Hughes (2020) pushed further.
They tested fifteen widely used measures directly against modern criteria. Most failed at least one basic check that had never actually been run before, despite years of unquestioned use.
Together, these findings suggest that convergent-validity evidence is claimed more often than it is actually checked.
FAQs
Is convergent validity internal or external?
Convergent validity is a form of construct validity, not external validity.
Construct validity asks whether a test or measure captures the underlying psychological construct it claims to assess. Convergent validity is one of two pieces of evidence, alongside discriminant validity, used to build that case.
External validity is a separate concept: it asks whether a study’s results generalize beyond the sample, setting, and time in which the data were collected, not whether one measure is accurate.
What is the difference between convergent and discriminant validity?
Discriminant validity indicates that the results obtained by an instrument do not correlate too strongly with measurements of a similar but distinctive trait. For example, say that a company is sending potential software engineers tests to measure how proficient they are at coding.
A high score on the coding test should not correlate strongly with the scores of an IQ test, as this would just make the coding test another IQ test.
Convergent validity, on the other hand, indicates that a test correlates with a well-established test’s measures of the same construct. Both discriminant and convergent validity are important for measuring construct validity (Hubley & Zumbo, 2013).
What is the difference between convergent and divergent validity?
Divergent validity is another name for discriminant validity. Some well-known writers in the measurement field use it (e.g., Nunnally & Bernstein, 1994), although it is not the commonly accepted term (Hubley & Zumbo, 2013).
Thus, the same differences exist between convergent and divergent validity and convergent and discriminant validity.
References
American Educational Research Association, American Psychological Association, & National Council on Measurement in Education. (2014). Standards for educational and psychological testing. American Educational Research Association.
Cronbach, L. J. (1951). Coefficient alpha and the internal structure of tests. psychometrika, 16(3), 297-334.
Elliott, M. L., Knodt, A. R., Ireland, D., Morris, M. L., Poulton, R., Ramrakha, S., Sison, M. L., Moffitt, T. E., Caspi, A., & Hariri, A. R. (2020). What is the test-retest reliability of common task-functional MRI measures? New empirical evidence and a meta-analysis. Psychological Science, 31(7), 792–806. https://doi.org/10.1177/0956797620916786
Firmin, Michael W., et al. “Evaluating the concurrent validity of three web-based IQ tests and the Reynolds Intellectual Assessment Scales (RIAS).” Eastern Education Journal 37.1 (2008): 20.
Flake, J. K., Pek, J., & Hehman, E. (2017). Construct validation in social and personality research: Current practice and recommendations. Social Psychological and Personality Science, 8(4), 370–378. https://doi.org/10.1177/1948550617693063
Hubley, A. M., & Zumbo, B. D. (2013). Psychometric characteristics of assessment procedures: An overview.
Hussey, I., & Hughes, S. (2020). Hidden invalidity among 15 commonly used measures in social and personality psychology. Advances in Methods and Practices in Psychological Science, 3(2), 166–184. https://doi.org/10.1177/2515245919882903
Krabbe, E. C. W. (2017). Validity in quantitative research: A practical guide to interpreting validity coefficients in scientific studies. Routledge Academic US Division: New York, NY 10017 USA. doi: 10.4324/9781315677620
Krefetz, D. G., Steer, R. A., Gulab, N. A., & Beck, A. T. (2002). Convergent validity of the Beck Depression Inventory-II with the Reynolds Adolescent Depression Scale in psychiatric inpatients. Journal of Personality Assessment, 78(3), 451-460.
MacDonald III, A. W., Goghari, V. M., Hicks, B. M., Flory, J. D., Carter, C. S., & Manuck, S. B. (2005). A convergent-divergent approach to context processing, general intellectual functioning, and the genetic liability to schizophrenia. Neuropsychology, 19(6), 814.
Nunnally, J. C., & Bernstein, I. H. (1994). Psychometric theory (3rd ed.). McGraw-Hill.
Poole, K. T., & Rosenthal, H. (1991). Patterns of congressional voting. American journal of political science, 228-278.
Spearman, C. (1904). The proof and measurement of association between two things. American Journal of Psychology, 15(1), 72–101. https://doi.org/10.2307/1412159
Watson, D., Clark, L. A., & Tellegen, A. (1988). Development and validation of brief measures of positive and negative affect: The PANAS scales. Journal of Personality and Social Psychology, 54(6), 1063–1070. https://doi.org/10.1037/0022-3514.54.6.1063