Open coding is the initial step in grounded theory research where you analyze data to identify and develop concepts that emerge from the information. It involves breaking down the data into smaller units and examining them closely to find meaningful segments.
Basic Steps
- Read before you code: go through the data once without coding anything, just to get a feel for the whole before fracturing it into parts.
- Begin coding by asking yourself “What is this about?” for each segment of text.
- Use either paper and highlighters or qualitative analysis software like NVivo or ATLAS.ti.
- Stay close to the data – avoid making big interpretive leaps early on.
- Code and collect data together: in grounded theory, coding the first interviews shapes who you recruit next, a strategy called theoretical sampling, rather than coding only once all the data is in.
At its core, open coding is about:
Going through your data line-by-line and identifying key ideas, actions, or events is the heart of the method. Open coding is data-driven and inductive: the researcher approaches the material without a pre-set coding frame. There is no checklist to fill in.
Of each segment, the analyst simply asks “What is this about?” (Strauss & Corbin, 1990; Glaser, 2016).
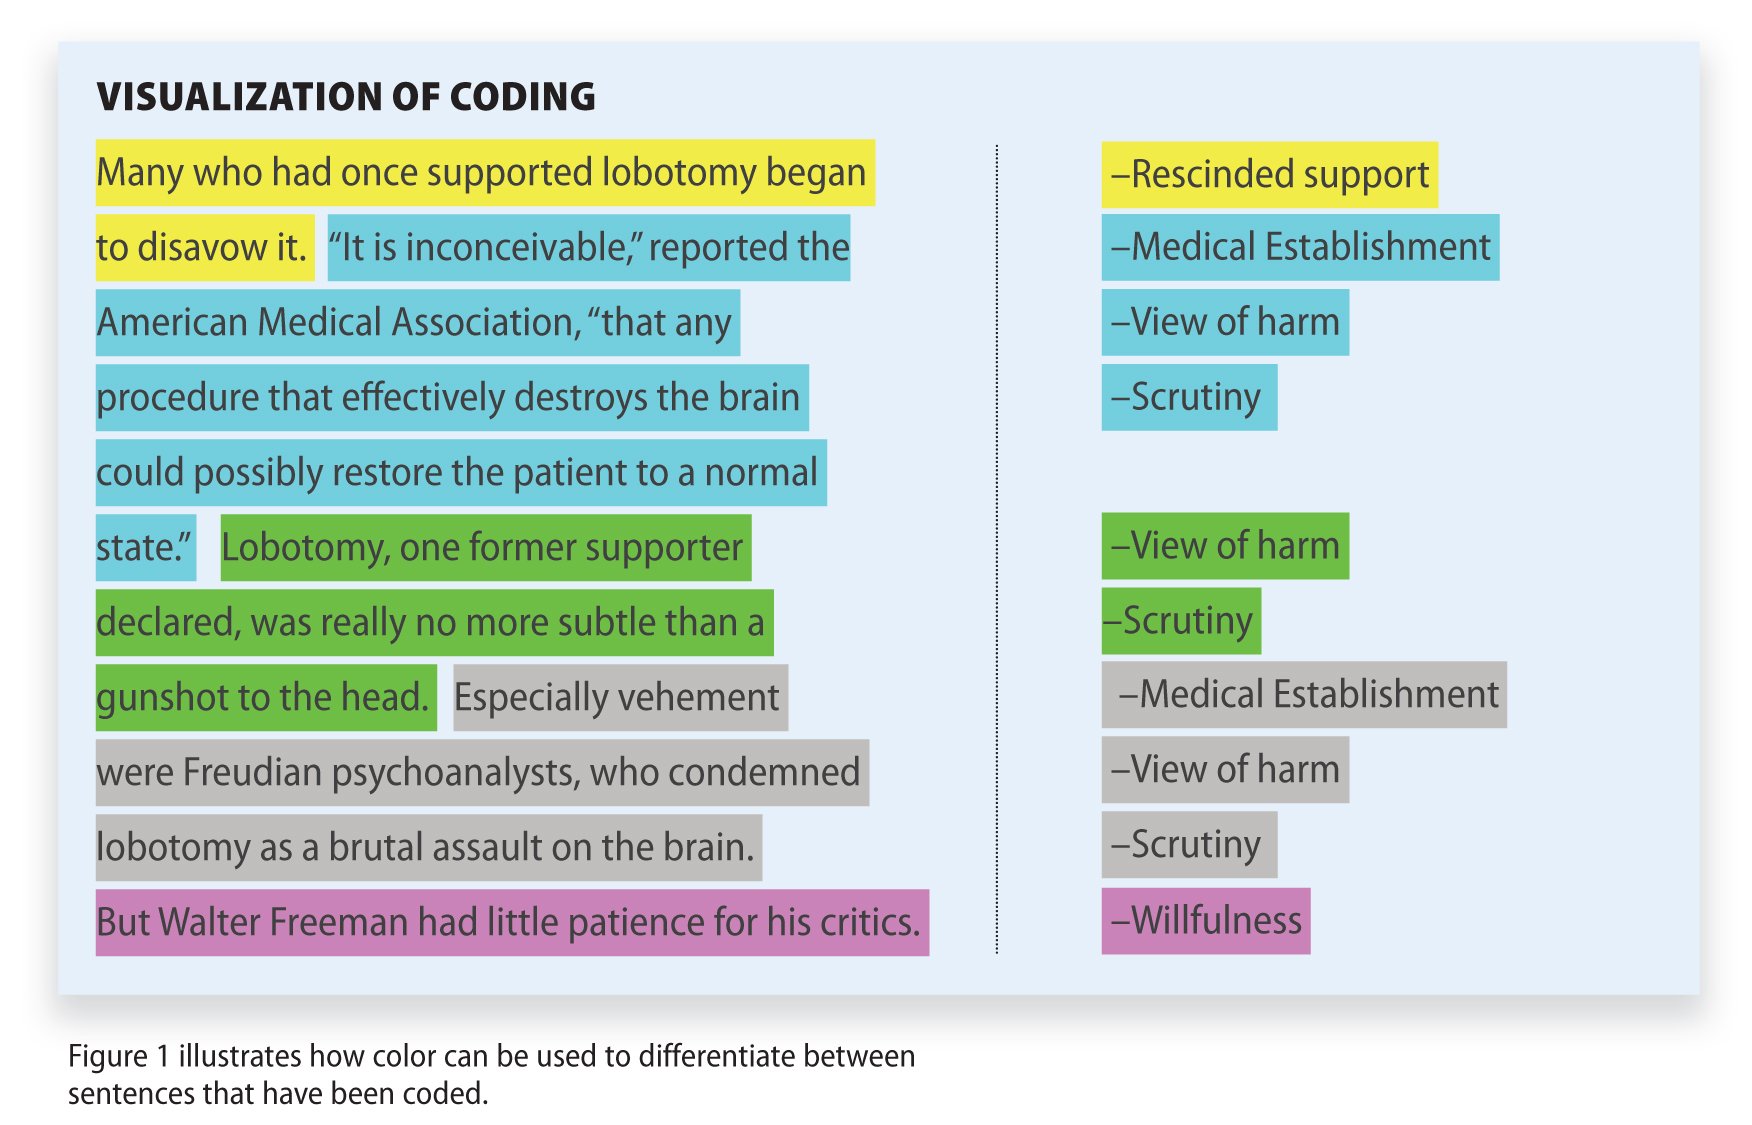
For each meaningful segment, you assign a “code” – a label or tag that captures what’s happening in that piece of data.
A short extract such as “I felt really nervous about starting my new job” might be coded workplace anxiety. Or it could stay in the participant’s own words.
Kept that way, it becomes an in-vivo code: a code taken directly from what they said, rather than from the analyst’s own language.
Three features set open coding apart from simply highlighting interesting quotes (Strauss & Corbin, 1990; Glaser & Strauss, 1967):
- It fractures the data: breaking the text apart, often line by line, forces the analyst to name what is happening rather than just summarising it.
- It is comparative: every new segment is checked against segments already coded, so similar incidents receive the same code.
- It is generative, not confirmatory: the aim is to discover concepts, not test a pre-existing hypothesis.
Analysts also decide how finely to fracture the data. Line-by-line coding codes almost every line of a transcript and suits interview data, because it stops the analyst leaping to broad interpretations too soon.
Incident-by-incident coding instead takes a whole episode or event as the unit. This fits field notes and observational data better than transcript “lines,” which are really just an artefact of typing up an interview.
Several kinds of code typically appear side by side:
- In-vivo codes: use the participant’s own words or phrases as the label, preserving meanings significant to them.
- Descriptive codes: summarise the topic of a passage in the analyst’s own words.
- Process codes: capture what people are doing, often as “-ing” words such as managing disclosure.
- Analytic codes: name a more abstract idea the segment points to, moving a step closer to theory.
A single segment can attract more than one code. Analysts are advised to over-code rather than under-code at this stage, since it’s easier to discard a redundant code later than to notice a missed pattern afterwards (Holton, 2007).
These codes categorise and organise the data, giving a foundation for further analysis. Open coding stays close to the data and lets concepts emerge, rather than imposing preconceived categories.
Origins in Grounded Theory
Open coding cannot be understood apart from grounded theory, the methodology in which it is the first step. Grounded theory was introduced by two American sociologists, Barney Glaser and Anselm Strauss. They published in 1967.
Open coding is the technique through which its central promise is carried out: building theory up from data, rather than testing ideas dreamed up in advance.
Glaser and Strauss (1967): The Discovery of Grounded Theory
Aim. Glaser and Strauss set out to challenge a mid-century sociology dominated by grand, untested theories, against which researchers merely gathered confirming data. Theory, they felt, should come from the ground up. They wanted to legitimise a different logic of inquiry: generating theory systematically from data itself.
Method. Rather than an experiment, their book distilled procedures drawn from their own fieldwork. It studied how hospital staff and dying patients managed awareness of dying. These included theoretical sampling, the constant-comparative method, coding data into concepts and categories, memo-writing, and continuing until theoretical saturation.
Results. Glaser and Strauss argued that categories and their relationships should be allowed to emerge from constant comparison. Nothing was fixed in advance.
A good grounded theory, on their account, is judged by whether it fits and works to explain the situation studied, not by the hypothesis-testing criteria of quantitative science.
Conclusion. The Discovery of Grounded Theory (1967) became one of the most influential methodological texts in the social sciences. Open coding is the operational heart of its alternative to hypothesis-testing. The book left the coding procedure only loosely specified, though. That gap later produced the schism described below.
The Straussian Formulation: Strauss and Corbin
Anselm Strauss first sketched an open, axial and selective coding sequence in 1987. He and Juliet Corbin then gave open coding its most detailed and widely taught formulation.
They defined it as “the process of breaking down, examining, comparing, conceptualizing, and categorizing data” (Strauss & Corbin, 1990). Most textbooks still use this definition. It is this Straussian formulation that most accounts of open coding reproduce.
A second edition followed in 1998. It expanded the guidance further, but kept the same core structure: open coding first, then axial coding, then selective coding, each building on the last. The order did not change.
The vocabulary changed more.
Strauss and Corbin also gave open coding a distinctive vocabulary that has stuck. Data breaks down into discrete “properties” and “dimensions,” building toward a single “core category” that ties the analysis together. That vocabulary is still how most textbooks describe the Straussian approach today.
Glaser’s Objection and Charmaz’s Reconstruction
Barney Glaser rejected the Strauss-Corbin codification. He argued that its prescribed steps forced data into pre-set frames rather than letting concepts emerge (Glaser, 1992). For Glaser, this was forcing, not discovery.
His alternative looked different from the start.
In his own scheme, open coding is the opening part of substantive coding, followed by theoretical coding. Here the analyst uses abstract “coding families” to weave codes into a theory. The theory earns its structure; it is not handed one.
Kathy Charmaz (2006) later reconstructed the approach on constructivist foundations, renaming the first phase initial coding. Codes, for her, are never neutral. She insisted that they are co-constructed by a situated, reflexive researcher, not simply discovered.
Three lineages, one shared root.
Straussian, Glaserian and constructivist open coding share the same starting move: fracturing data into codes by constant comparison. That much is common ground. They disagree, however, about almost everything that follows.
What is the purpose of open coding?
The goal of open coding is to:
- Become familiar with the data through multiple readings of the transcripts, field notes, or other qualitative data.
It is about immersion and exploration, letting researchers move past superficial readings to engage with the richness and complexity of their data.
- Identify and label key concepts, ideas, and themes relevant to the research question.
- Develop a system for categorizing and organizing the data to reduce it to a manageable size.
- Uncover salient concepts, phenomena, relationships, and positive and negative cases.
Open coding is a crucial first step in qualitative data analysis. It allows for a thorough, systematic examination of the data, which leads to the key themes that guide further analysis.
Through this systematic approach, open coding is fundamentally data-driven and inductive, prioritizing close engagement with the data and allowing concepts to surface naturally rather than imposing preexisting frameworks.
Example of Open Coding
Here is an example of open coding:
Let’s imagine a researcher is conducting a study exploring the experiences of nurses working in intensive care units during the COVID-19 pandemic.
The researcher collects the data first. It comes from in-depth interviews with a group of nurses.
During open coding, the researcher reads through the interview transcripts line by line, identifying and labeling meaningful segments of data related to the research question.
Here’s an example of how open coding might be applied to a specific excerpt from an interview transcript:
Excerpt from Interview Transcript:
“It was just overwhelming. We had so many patients, and they were all so sick. We were constantly running around, trying to keep up with everyone’s needs. It felt like we were always one step behind.”
Open Codes:
- Workload: This code captures the nurse’s description of a heavy workload with many patients to care for.
- Patient acuity: This code reflects the nurse’s observation that the patients were very ill, requiring intensive care.
- Time pressure: This code highlights the nurse’s sense of urgency and feeling rushed to meet patient needs.
- Feeling overwhelmed: This code encapsulates the nurse’s overall emotional state of feeling overwhelmed by the situation.
As the researcher continues to code the data, they would identify additional codes related to other aspects of the nurses’ experiences, such as:
- Emotional exhaustion
- Moral distress
- Teamwork and support
- Coping mechanisms
The researcher continues this process across all the transcripts. Over time it builds a comprehensive codebook that captures the range of experiences, thoughts, and feelings the nurses described.
The real work happens through constant comparison: checking each new segment against segments already coded. Nothing is coded in isolation. If a second nurse describes feeling “one step behind” in a similar way, it takes the same code, time pressure, rather than a new one.
As codes build up, the researcher clusters related ones into broader categories. Workload, patient acuity and time pressure might cluster together. Together they could form a category such as “an unmanageable caseload.”
That category is then developed in terms of its properties: its characteristics, such as how many patients and how sick they are.
It is also developed in terms of its dimensions. These are the range each property covers, from just-manageable to overwhelming.
Throughout, the researcher keeps memos: short, dated notes capturing ideas about a code, comparisons between incidents, and hunches about how categories might relate. Nothing is too small to jot down. A memo is where a code first grows into a theoretical idea, rather than staying just a label.
tips for effective open coding
- Read the data multiple times: Immerse yourself in the data and read through the transcripts, field notes, or other data sources multiple times.
- Stay close to the data: Avoid imposing preconceived ideas or theoretical frameworks. Instead, let the data guide the coding process.
- Code for as many concepts as possible, even those that seem insignificant at first: Initially, it’s better to over-code than to under-code. This ensures that you capture the full range of ideas and perspectives present in the data.
- Use a variety of coding techniques:
- In vivo codes: In vivo codes use the participants’ own words or phrases as codes. This helps preserve the richness and authenticity of their voices.
- Descriptive codes: Use descriptive codes to summarize or paraphrase the meaning of larger segments of text.
- Process codes: These capture actions, interactions, or processes described in the data, focusing on what is happening rather than static concepts.
- Consider the context: Always interpret codes within the context of the data. Consider who said it, when it was said, and the surrounding circumstances.
- Be flexible and iterative: Be open to refining or adjusting codes as you progress through the data. Open coding is an iterative process, and your understanding of the data will evolve over time.
- Reflect on your own biases. Qualitative research is inherently subjective, and your own experiences and perspectives will inevitably influence your coding decisions. Practice reflexivity, acknowledging your biases, and considering how they might be shaping your interpretation of the data
- Document your decisions: Keep a record of your coding decisions and the rationale behind them. This will enhance the transparency and rigor of the analysis.
Can qualitative data analysis software be used for open coding?
Yes, qualitative data analysis software (QDAS) can be valuable for open coding, especially when dealing with large or complex datasets.
Programs like NVivo and Atlas.ti are specifically designed to support various aspects of qualitative data analysis, including open coding.
These software tools provide features that can significantly enhance the efficiency and rigor of the open coding process.
Some of the benefits of using QDAS for open coding include:
- Efficient Data Management: QDAS allows researchers to import and organize various data formats, including interview transcripts, field notes, documents, and even multimedia files. This centralized platform facilitates easy access and navigation of the data during coding.
- Streamlined Coding Process: QDAS provides functionalities for highlighting segments of text and attaching codes to them. The software typically allows for creating and managing a codebook within the program, enabling researchers to develop and refine codes as they progress through the data.
- Hierarchical Coding Structures: QDAS enables researchers to organize codes into hierarchical structures, creating parent and child codes to represent relationships between broader concepts and their sub-themes. This hierarchical organization aids in developing a more comprehensive and nuanced understanding of the data.
- Code Searching and Retrieval: Researchers can easily search for specific codes or combinations of codes across the entire dataset. This functionality enables quick access to all data segments associated with a particular concept, facilitating the identification of patterns and comparisons across the data.
- Visualization of Relationships: Many QDAS programs offer visualization tools, such as mind maps or network diagrams, to illustrate the relationships between codes and themes. These visual representations can help researchers identify connections and develop a deeper understanding of the conceptual landscape emerging from the data.
- Team Collaboration: Some QDAS software supports collaborative coding, allowing multiple researchers to work on the same project simultaneously. This can facilitate consistency in coding and expedite the analysis process for larger teams.
While these tools can be helpful, especially with large datasets, it is crucial to remember that they are simply tools and do not replace the researcher’s interpretive judgment.
The researcher remains responsible for making decisions about how to code the data and how to interpret the meaning of the codes.
How do I know when I am finished with open coding?
There is no fixed endpoint or “magic formula” for determining when open coding is complete.
It is an iterative process guided by the researcher’s judgment and the emerging patterns in the data.
However, several indicators can help you assess whether you have reached a point of saturation in open coding:
- No New Codes Emerging: As you continue to code data, you will reach a point where you are no longer identifying new concepts or themes. The existing codes in your codebook become sufficient to capture the range of ideas and experiences expressed in the data. This stabilization of the coding structure, known as code data saturation, indicates that you have likely reached a comprehensive understanding of the key concepts within your data.
- Meaning Saturation: Beyond code saturation, meaning saturation is achieved when the data no longer reveals new nuances or dimensions of the existing codes and themes. You have a deep understanding of the relationships between the codes, and the data offers no further insights into the complexities of the phenomena you are studying.
- Confidence in Explanatory Power: You feel confident that the codes you have developed can adequately explain the patterns and variations observed in the data. Your codebook provides a robust framework for understanding the participants’ perspectives and experiences.
- Alignment with Research Question: The codes and themes you have identified are clearly aligned with your research question, providing a rich foundation for addressing your research objectives. You feel that the open coding process has yielded sufficient conceptual material to move forward with answering your research question.
Saturation is not an absolute state, though.
Depending on the aims of the analysis or the level of detail desired, you may revisit and refine your codes even after reaching a perceived saturation point.
Several factors can influence the point at which you reach saturation in open coding:
- Dataset Size and Complexity: Larger and more diverse datasets generally require more time and coding to reach saturation.
- Researcher Experience: Experienced researchers may reach saturation more quickly, as they are more familiar with recognizing patterns and identifying relevant concepts.
- Research Objectives: The level of detail required to address your research question will influence how extensively you need to code your data.
Regularly reflect on your coding progress and assess whether you are still gaining new insights from the data.
If you find that coding is becoming repetitive and no new concepts are emerging, it may be a sign that you are approaching saturation.
There’s no shortcut here.
Remember that open coding is the foundation for subsequent stages of qualitative analysis.
It is crucial to invest sufficient time and effort in this stage to develop a robust and nuanced understanding of your data.
What happens after open coding?
After the foundational stage of open coding, the next step in qualitative data analysis is to transition into focused coding.
- Focused coding involves systematically reviewing the codes generated during open coding and identifying the most significant and frequent codes that directly relate to the research question
- Axial coding goes beyond simply categorizing codes into themes. It involves a deeper exploration of the relationships and connections between categories. This stage focuses on:
- Combining themes: Axial coding looks for ways to connect or integrate themes that share underlying concepts or patterns.
- Assigning data to multiple themes (cross-coding): Recognizing that certain segments of data may contribute to multiple themes or concepts, axial coding allows for a more nuanced understanding of the interconnectedness of ideas.
Focused coding provides the thematic structure that axial coding then builds upon. “Focused coding” is Kathy Charmaz’s (2006) term for this second step. The Straussian tradition instead calls it axial coding outright. Simply Psychology follows this blended, commonly taught vocabulary rather than any single purist lineage.
Open Coding vs Thematic Analysis
Open coding is often confused with the coding done in thematic analysis. The two are not the same thing. They share a family resemblance, though: both attach codes to segments of data and build upward towards broader structures.
The real difference is what each is for.
Thematic analysis (Braun & Clarke, 2006) is a stand-alone method for describing patterns of meaning, or “themes,” and its endpoint is a narrative built around them. Open coding aims higher. It is instead one step inside grounded theory, whose endpoint is an integrated explanatory theory.
Grounded-theory coding is also interleaved with data collection: each round of coding shapes the next round of sampling. Thematic analysis usually works differently. It typically codes a dataset gathered in advance.
Critical Evaluation of Open Coding
Open coding converts unstructured talk and text into analysable concepts through inductive labelling and constant comparison. Its value is that it lets theory be built from data and discovers what a pre-set frame would miss, but it is also slow, subjective, and internally contested.
Both sides of that trade-off are worth spelling out.
Strengths
- Grounded in the data: because codes build up from participants’ own accounts rather than prior theory, the resulting concepts fit the material closely, which is especially useful in under-researched areas.
- Discovers the unexpected: fracturing the data and asking “what is happening here?” surfaces processes the researcher did not anticipate, the opposite of the confirmation-seeking risk in hypothesis-testing designs.
- Systematic and transparent: constant comparison, memoing and the codes-to-categories ladder create a documented analytic trail that others can inspect.
- Keeps meaning close to participants: in-vivo coding and line-by-line attention reduce the risk that the analyst’s own categories silently replace participants’ meanings.
- Theory-generating: open coding is explicitly a route to new theory rather than description alone, which is why grounded theory remains a leading choice for building explanatory models.
Limitations and Debates
Open coding’s demands are also its main weaknesses. The same close, inductive fracturing that keeps the analysis grounded in the data is what makes it slow, effortful, and dependent on the analyst’s own judgement:
- Labour-intensive: line-by-line coding of many transcripts, interleaved with further data collection, is extremely demanding of time and expertise.
- Researcher subjectivity: because the analyst is the coding instrument, another researcher may fracture and label the same data differently.
- The fragmentation critique: breaking an account into hundreds of codes can destroy its narrative coherence, cutting a person’s story into disconnected fragments.
- The Glaser-Strauss schism: the method’s own founders split over how open coding should proceed, so there is no single agreed procedure.
- The saturation debate: what “saturation” means, and how a researcher can demonstrate rather than merely assert it, is genuinely contested.
The Fragmentation Critique
Critics of grounded theory, and advocates of narrative and phenomenological approaches, argue that fracturing an account into hundreds of codes can destroy its narrative coherence. The connections between events in a person’s story get lost.
Grounded theorists reply that constant comparison and memoing put the pieces back together at a higher, theoretical level. The tension is real, though.
A transcript fractured into fifty codes is genuinely harder to read as one coherent account than the original interview was. How much theoretical reassembly compensates for that loss is a matter of judgement, not a settled fact.
The Glaser-Strauss Schism
Glaser’s (1992) charge was that Strauss and Corbin’s prescribed procedures force data into pre-set frames, producing “conceptual description” rather than genuine grounded theory. That means there is no single agreed version of open coding: which one counts as “correct” depends on which lineage, Glaserian, Straussian or constructivist, a researcher adopts.
Neither side has ever conceded the point.
Glaserians and constructivists also draw opposite lessons from researcher subjectivity. Glaser (1978) trusts a disciplined analyst to let concepts emerge, while Charmaz (2006) treats subjectivity as impossible to eliminate and to be handled through reflexivity instead. Either way, codes are not simply “read off” the data.
The Saturation Debate
Open coding is supposed to stop at theoretical saturation. In practice, though, it is often conflated with simple data saturation (the mere repetition of content) or reduced to a fixed interview count.
The two are not the same thing.
One widely cited experiment found the main themes of a homogeneous sample were largely present within twelve interviews (Guest, Bunce, & Johnson, 2006). That sits awkwardly with grounded theory’s own insistence that saturation concerns the development of categories, not a tally of repeated content, as the next section explains.
Contemporary Research
Recent methodological work runs in two directions. One strand tightens the theoretical basis for the classic stopping rule; the other sets out how to run open coding rigorously outside sociology.
Two recent papers show each strand at work.
Clarifying Saturation
Aim. Saunders et al. (2018) set out to clarify the widely used but loosely defined concept of saturation. They wanted to specify how it should be operationalised consistently with a study’s own methodology.
Method. Rather than an empirical study, this was a conceptual and methodological analysis. The authors reviewed how “saturation” is defined and applied across the qualitative literature, building a typology of its meanings.
No new data were collected.
Results. They identified four distinct models: theoretical saturation (the grounded-theory sense, tied to theoretical sampling), inductive thematic saturation, a priori thematic saturation, and data saturation. Which one applies depends on the analytic approach being used.
Conclusion. For open coding specifically, coding should stop when the categories, their properties and dimensions, are fully developed through theoretical sampling, not simply when interviews start to sound repetitive.
Open Coding in Applied Health Research
Aim. Foley and Timonen (2015) set out the key components of grounded theory, including open coding, for researchers new to applying the method to patients’ and providers’ experience of health care.
Method. A methodological paper rather than a fresh empirical report, illustrated with the authors’ own grounded-theory study of how people with amyotrophic lateral sclerosis (ALS) experienced health-care services.
Results. They showed that grounded-theory approaches work particularly well for “hard-to-reach” population groups and previously unstudied topics. Open coding’s flexibility lets a theory of service engagement build up from the data itself, rather than being tested against it.
Conclusion. Open coding, as grounded theory’s point of entry, lets researchers capture health-care experiences with structure and analytic rigor. The paper is now a widely used practical reference for applying open coding in health-services research.
Key Takeaways
- Definition: open coding is the first analytic step in grounded theory: breaking data into segments and attaching a short conceptual label, or “code,” to each one.
- Origins: the method comes from Glaser and Strauss’s 1967 book The Discovery of Grounded Theory; Strauss, Glaser and Charmaz later split over how it should be done.
- Code Types: codes can stay in participants’ own words (in-vivo), describe a topic, capture an action, or name an abstract concept.
- Constant Comparison: every new segment is compared with segments already coded, which is what turns a pile of codes into organised categories.
- Software: tools like NVivo and ATLAS.ti make the mechanics easier but do not replace the researcher’s judgement.
- Stopping Point: coding continues until theoretical saturation, though Saunders et al. (2018) show “saturation” is used to mean several different things depending on the method.
Reading List
- Birks, M., & Mills, J. (2015). Grounded theory: A practical guide. Sage.
- Braun, V., & Clarke, V. (2006). Using thematic analysis in psychology. Qualitative Research in Psychology, 3(2), 77-101.
- Charmaz, K. (2006). Constructing Grounded Theory: A practical guide through Qualitative Analysis. Thousand Oaks, California: Sage.
- Corbin, J., & Strauss, A. (1990). Grounded theory research: Procedures, canons, and evaluative criteria. Qualitative Sociology, 13, 3-21.
- Foley, G., & Timonen, V. (2015). Using grounded theory method to capture and analyze health care experiences. Health Services Research, 50(4), 1195-1210.
- Glaser, B. G. (1978). Theoretical sensitivity: Advances in the methodology of grounded theory. Sociology Press.
- Glaser, B. G. (1992). Basics of grounded theory analysis: Emergence vs. forcing. Sociology Press.
- Glaser, B. G. (2016). Open Coding Descriptions. Grounded theory review, 15(2).
- Glaser, B. G., & Strauss, A. L. (1967). The discovery of grounded theory: Strategies for qualitative research. Aldine.
- Holton, J. A. (2007). The coding process and its challenges. The Sage handbook of grounded theory, 3, 265-289.
- Khandkar, S. H. (2009). Open coding. University of Calgary, 23(2009), 2009.
- Saunders, B., Sim, J., Kingstone, T., Baker, S., Waterfield, J., Bartlam, B., Burroughs, H., & Jinks, C. (2018). Saturation in qualitative research: Exploring its conceptualization and operationalization. Quality & Quantity, 52(4), 1893-1907.
- Strauss, A., & Corbin, J. (1990). Basics of qualitative research: Grounded theory procedures and techniques. Sage.
- Strauss, A. L., & Corbin, J. (2004). Open coding. Social research methods: A reader, 303-306.