The experimental method involves the manipulation of variables to establish cause-and-effect relationships. The key features are controlled methods and the random allocation of participants, assigning them to groups purely by chance, into controlled and experimental groups.
Key Takeaways
- Cause and Effect: A true experiment needs a manipulated independent variable, a measured dependent variable, and random assignment to conditions. No other research method can establish cause and effect this confidently.
- Four Main Types: Laboratory, field, natural, and quasi experiments trade off control against realism. Lab experiments give the most control; natural and quasi experiments study variables, like age or a real-world event, that cannot be manipulated.
- Control Protects Validity: Randomisation and standardised procedures rule out other explanations, protecting internal validity: confidence that the IV, not something else, caused the change in the DV.
- Being Observed: Participants can pick up on demand characteristics, cues that hint at what a study is testing, and change their behaviour. Experimenters can also unintentionally bias results through their own expectations, and blinding guards against both.
- Ethical Limits: Ethical rules, like informed consent and protection from harm, limit what researchers can manipulate directly. Variables such as trauma or an existing illness can only be studied through natural or quasi experiments.
- Replication: A large project that re-ran 100 psychology studies found only about a third to a half of the results held up (Open Science Collaboration, 2015). Read any single study’s conclusions with some caution.
What is an Experiment?
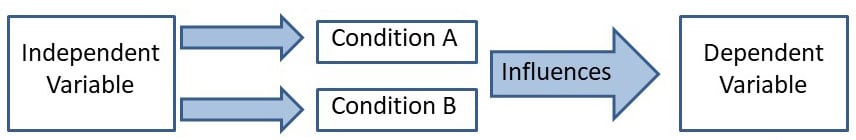
An experiment is an investigation in which a hypothesis is scientifically tested. An independent variable (the cause) is manipulated in an experiment, and the dependent variable (the effect) is measured; any extraneous variables are controlled.
A study only counts as a true experiment if it has three key ingredients:
- Manipulation of the IV: the researcher creates at least two conditions to compare, so a difference can be demonstrated.
- Measurement of the DV: the outcome is given a clear, measurable definition.
- Random assignment: participants are randomly allocated to conditions, so the groups differ only in the way the researcher intended.
If any of these three ingredients is missing, the study is not a true experiment. For example, if the IV occurs naturally rather than being manipulated, it becomes a natural or quasi experiment instead.
Extraneous variables are factors other than the IV. They could still affect the results, such as noise or a participant’s mood. Researchers control these so they do not become confounding variables that offer an alternative explanation for the findings.
A caffeine experiment shows these parts working together. The aim is to find out whether caffeine increases stress.
| Element | In the caffeine experiment |
|---|---|
| Independent variable | How much caffeine is in the coffee each participant drinks |
| Dependent variable | Each participant’s score on a stress questionnaire |
| Research hypothesis | A large caffeine dose leads participants to report more stress |
| Null hypothesis | Reported stress is the same with a large dose as with no caffeine |
| Possible confounds | Caffeinated drinks consumed before the study; stress caused by the experimental setting itself |
Other factors could also change stress levels, so the design uses three groups. A treatment group drinks caffeinated coffee, a control group drinks nothing, and a placebo control group drinks decaffeinated coffee.
The placebo group helps rule out the effect of participants’ expectations. That matters most in drug trials.
Experiments aim to be objective, so the researcher’s views and opinions should not affect a study’s results. Objectivity makes the data more valid and less biased.
Experimental Designs
An experimental design describes how participants are allocated to the conditions of the independent variable. There are three main options.
- Independent groups: Each participant takes part in one condition only, usually through random allocation. This avoids order effects, but it needs more participants and the groups may differ.
- Repeated measures: The same participants take part in every condition. Participant variables are perfectly controlled and fewer people are needed, but practice or tiredness can create order effects.
- Matched pairs: Each participant takes part in one condition, but participants are paired on a relevant factor, such as age or ability. Matching is time-consuming and never perfect.
Counterbalancing reduces order effects in repeated measures designs. Half the participants complete condition A first, and half complete condition B first.
Types of Experiments
There are four types of experiments you need to know:
1. Lab Experiment
A laboratory experiment is conducted under highly controlled conditions (not necessarily a laboratory) where accurate measurements are possible.
The researcher uses a standardized procedure to determine where the experiment will take place, at what time, with which participants, and in what circumstances.
Participants are randomly allocated to each independent variable group.
Examples are Milgram’s experiment on obedience and Loftus and Palmer’s (1974) car crash study. Loftus and Palmer’s study shows the method in miniature: one changed word altered what witnesses remembered.
- Aim: To test whether the wording of a question asked after an event could distort memory of the event itself.
- Method: In Experiment 1, 45 students watched car-crash films, then estimated speed after a question using one of five verbs. In Experiment 2, a week later, students were asked about broken glass; the film showed none.
- Results: Estimates averaged 40.8 mph for “smashed” and 34.0 mph for “hit.” A week later, 32% of the “smashed” group falsely recalled broken glass, versus 14% for “hit” and 12% for controls.
- Conclusion: A leading question can alter the memory itself, not just what a witness chooses to say. Only the verb changed, so the verb caused the difference.
The tight control supports the causal claim. Yet watching a staged film is calmer than witnessing a real crash.
The verb effect also depends on the setting. In a 2017 sport replication, students who later read a hockey collision described as “contact,” “bump” or “smash” gave similar estimates of skating speed (Goldschmied et al., 2017).
- Strength: A laboratory experiment is easier to replicate because it uses a standardized procedure.
- Strength: Precise control of extraneous and independent variables lets researchers establish a cause-and-effect relationship.
- Limitation: An artificial setting can produce unnatural behavior, giving the study low ecological validity and findings that may not generalize to real life.
- Limitation: Demand characteristics or experimenter effects may bias the results and become confounding variables.
2. Field Experiment
A field experiment takes place in the participant’s own everyday setting, not a lab. The experimenter still manipulates the independent variable and measures its effect on the dependent variable, just as in a laboratory study.
Control is harder to achieve outside the lab. Participants are often unaware they are being studied, and the experimenter has less control over extraneous variables.
Field experiments are common in social psychology. Researchers have used them to study altruism, obedience, and persuasion, and to test real-world interventions such as educational programs and public health campaigns.
Hofling et al. (1966) is the classic example: an obedience study set in a real hospital.
- Aim: To see whether nurses would obey an order from an unfamiliar “doctor” that broke hospital rules.
- Method: An unknown caller posed as a doctor. He telephoned nurses on duty and told them to give a patient an overdose of an unauthorised drug.
- Results: 21 of the 22 nurses obeyed and started to administer the overdose before being stopped.
- Conclusion: Real nurses obeyed an illegitimate order from an authority figure in their normal workplace. Obedience to authority happens outside the laboratory too.
- Strength: A field experiment’s natural setting gives it higher ecological validity than a lab experiment, so behavior is more likely to reflect real life.
- Strength: Demand characteristics are less likely to affect the results, as participants may not know they are being studied. This occurs when the study is covert.
- Limitation: Researchers have less control over extraneous variables that might bias the results, making the study harder to replicate exactly.
3. Natural Experiment
A natural experiment studies an event that occurs naturally, without the researcher manipulating anything. The event does the manipulating, not the experimenter.
The experimenter simply observes changes in the dependent variable as it unfolds, in the participant’s own everyday environment. The researcher has no control over the independent variable itself.
Natural experiments often study phenomena that would be too rare, or too unethical, to stage in a lab: natural disasters, policy changes, social movements. No ethics committee would approve manipulating them directly.
For example, Hodges and Tizard’s attachment research (1989) compared the long-term development of adopted, fostered, and reunited children. A control group had spent their whole lives with their biological families.
Williams (1986) took the same logic to a whole town.
A Canadian community nicknamed “Notel” had just gained television for the first time, giving researchers a rare before-and-after comparison. Nobody switched on Notel’s first set for the study; the event simply happened.
Verbal and physical aggression among 6-11-year-olds rose over the two years after TV arrived, while it stayed flat in nearby towns that already had television.
Charlton and Hannan (2005) later studied St. Helena. This isolated community only gained television when CNN arrived there in 1995. They followed nearly 800 school-age children. Their findings challenged the simple claim that television alone drives antisocial behaviour.
- Strength: Because natural experiments study real-world events, they have very high ecological validity and reflect real life closely.
- Strength: Demand characteristics are less likely to affect the results, as participants may not know they are being studied.
- Strength: It can be used in situations in which it would be ethically unacceptable to manipulate the independent variable, e.g., researching stress.
- Limitation: They may be more expensive and time-consuming than lab experiments.
- Limitation: There is no control over extraneous variables that might bias the results. This makes it difficult for another researcher to replicate the study in exactly the same way.
4. Quasi Experiment
A quasi experiment studies an independent variable that already exists, such as age, gender, or a diagnosed condition. These characteristics cannot be manipulated or randomly assigned, so participants arrive already sorted into their groups.
Because random allocation is not possible, an unknown participant variable could explain the results instead of the IV. This lowers the validity of any cause-and-effect conclusion.
For example, comparing memory scores between younger and older adults is a quasi experiment. Age is the IV, but the researcher cannot assign people to be young or old.
- Strength: It allows psychologists to study variables, like gender or a mental health diagnosis, that could never ethically or practically be manipulated.
- Limitation: Without random allocation, participant variables between the groups may explain the results instead of the IV, weakening any cause-and-effect claim.
The table below compares all four types of experiment.
| Type | Who controls the IV? | Setting | Random allocation? | Main strength | Main limitation |
|---|---|---|---|---|---|
| Laboratory | Researcher | Controlled | Yes | High control and reliability | Low ecological validity |
| Field | Researcher | Natural | Sometimes | Higher ecological validity | Less control over extraneous variables |
| Natural | Nature or events | Natural | No | Studies rare or unethical-to-manipulate events | Hard to replicate; no random allocation |
| Quasi | Pre-existing characteristic | Any | No | Studies variables that cannot be manipulated | Reduced validity; no random allocation |
Key Terminology
- Ecological validity: How far a study’s findings apply to real-life settings beyond its own artificial conditions. Highly controlled lab studies often score low here, even when internal validity is high.
- Experimenter effects: The way a researcher’s own expectations can unintentionally shape a study’s outcome. Small differences in tone or manner toward participants can matter, with no deliberate intent to bias results.
- Demand characteristics: Cues in a study, like the setting or the experimenter’s manner, that let a participant guess what is being tested. Participants may then change their behaviour to fit, or deliberately defy, that guess.
- Independent variable (IV): The variable a researcher deliberately manipulates, on the assumption that it directly affects the outcome being measured.
- Dependent variable (DV): The variable a researcher measures, to see whether its value was affected by the independent variable.
- Operationalisation: Turning an abstract concept into something measurable. Happiness is hard to measure directly, but the number of times a person smiles in two hours is not. Clear measures also let other researchers replicate the study.
- Extraneous variables (EV): Any variable, other than the IV, that could affect the results, whether a trait of the participants (age, intelligence) or of the situation (noise, lighting).
- Confounding variables: An extraneous variable that has not been controlled and that varies systematically with the IV, not just randomly. Because it moves in step with the IV, its effect on the DV is easily mistaken for the IV’s own effect.
- Random allocation: Assigning participants to conditions purely by chance, so the only systematic difference between groups is the one the researcher intends. This spreads other participant differences evenly, rather than letting them bias one group.
- Order effects: Changes in a participant’s performance from repeating the same or similar test more than once. A practice effect is an improvement from growing familiar with the task; a fatigue effect is a decline from boredom or tiredness. This is why repeated measures designs use counterbalancing: half the participants complete the conditions in one order, half in the other, so practice and fatigue cancel out for everyone.
Demand Characteristics and Investigator Effects
Demand Characteristics
Participants are not passive in an experiment. Orne (1962) showed that people actively pick up on cues in the situation, such as the instructions or the experimenter’s manner. They read the room. From these cues, they work out what the study is testing.
Participants who spot these demand characteristics often try to be a “good participant” and behave in the way they think the researcher wants. This can create the Hawthorne effect, where people perform differently simply because they know they are being watched.
That single insight still shapes how studies are designed today.
Even a classic study can be read this way. Critics have argued that some participants in Milgram’s (1963) obedience experiments worked out the shocks were not real. They kept going only because that seemed to be what the study wanted from them (Orne & Holland, 1968).
A modern study complicates this critique.
In a virtual-reality version of Milgram’s paradigm, 40 participants tried to help the Learner more than 20 controls who did not take part in the simulation.
Participants who identified more with the science helped more and hesitated longer before pressing the shock button (Gonzalez-Franco et al., 2018). The authors read this as evidence for “engaged followership” rather than an “agentic state.”
Investigator Effects
Experimenters can bias results too, without meaning to. Rosenthal and Fode (1963) told researchers that their laboratory rats had been bred to be either “maze-bright” or “maze-dull”.
In reality, the rats had been randomly allocated. The bright rats still learned the maze faster, simply because the researchers’ expectations changed how they handled the animals.
The same investigator effect works on people, not just rats.
Rosenthal and Jacobson (1968) told teachers that certain randomly chosen pupils were about to “bloom” academically. Those pupils later showed significantly greater IQ gains than their classmates.
The only real difference was the expectation the teachers had been given, a self-fulfilling prophecy that shaped how they treated the children.
Researchers guard against these biases with blinding. There are two levels.
- Single-blind: Participants do not know which condition they are in.
- Double-blind: Neither the participants nor the researcher running the session knows. This stops experimenter expectations from influencing the results.
Applications of the Experimental Method
The same logic of manipulating one variable, measuring an outcome and allocating participants by chance reaches far beyond psychology labs. Three fields show how.
Medicine and Policy: Randomized Trials
The randomized controlled trial (RCT) is the experimental method applied to medicine. The Medical Research Council’s (1948) streptomycin trial is widely credited as the first published RCT.
Researchers randomly allocated patients with pulmonary tuberculosis to receive streptomycin or standard bed rest. The independent variable was the drug. The dependent variables were radiological improvement and mortality.
Random allocation stopped sicker or more resilient patients from ending up mostly in one group. Modern drug trials follow the same template, usually adding a placebo and double-blinding to control expectations.
Governments and aid agencies apply the same logic to social policy. Banerjee and Duflo (2009) reviewed randomized evaluations in development economics.
Villages, schools or households were randomly allocated to an intervention or a control condition. Typical interventions include cash transfers and deworming programmes.
Allocation by chance separates a policy’s real effect from the selection effects that distort simple before-and-after comparisons.
Education: The Testing Effect
Findings from controlled memory experiments feed directly into how revision is designed. Roediger and Karpicke (2006) tested whether a practice test helps learning more than studying again.
Students read prose passages, then either restudied them or took one or three free-recall tests with no feedback. The independent variable was restudying versus testing. The dependent variable was recall after 5 minutes, 2 days or 1 week.
Restudying won after 5 minutes. After longer delays, the tested students remembered substantially more, even though restudying had made the other group feel more confident.
The comparison isolates retrieval practice, rather than mere exposure, as the active ingredient in lasting learning. That is why study advice now says to test yourself instead of rereading your notes.
Technology: Fitts’s Law and A/B Tests
Experiments also shape the screens people use every day. Fitts (1954) had participants move a stylus back and forth between two targets of different widths and distances.
Target size and distance were the independent variables. Movement time was the dependent variable. The result was a lawful relationship between a target’s size, its distance and how quickly it can be hit.
Designers still rely on it. It helps decide how large, and how far apart, buttons and links should be.
Technology companies now run the same design at industrial scale as A/B tests. Users see one of two page versions, chosen at random. A behaviour such as clicks or purchases is then compared between versions (Kohavi et al., 2009).
The structure is that of a laboratory experiment: a manipulated variable, a measured outcome and random allocation. The sample can run to millions of users.
Critical Evaluation of the Experimental Method
The experimental method is the most powerful tool psychology has for showing cause and effect, but that power comes with real trade-offs.
Strengths of the Experimental Method
- Only Route to Cause and Effect: Manipulating the IV and randomly allocating participants rules out reverse causation and spreads other differences between groups by chance. No other method family can claim this as confidently.
- High Reliability: Standardised procedures and clear operational definitions make experiments easy to repeat, so results can be checked and confirmed by other researchers.
- Precision: Quantitative dependent variables allow statistical testing, and let findings from separate studies be pooled together, which is how a field builds confidence in an effect over time.
- Flexibility: The method spans the tight control of the laboratory and the realism of the field. Natural experiments even reach events, like a town gaining television for the first time, that could never ethically be staged on purpose.
Limitations of the Experimental Method
- Artificiality: Laboratory control can trade away ecological validity. A contrived task, like judging a filmed car crash, may not reflect how people behave in everyday life.
- The Experiment Is a Social Situation: Participants actively interpret demand characteristics, and experimenters can unintentionally shape results through their own expectations. Blinding reduces this problem but cannot remove it entirely.
- Restricted Scope: Many of psychology’s most important variables, such as age, trauma, or culture, cannot be manipulated. This forces a shift to natural or quasi experiments, whose lack of random allocation weakens any cause-and-effect claim.
- Ethical Constraints: Rules on consent, deception, and protection from harm properly limit what a researcher can manipulate. A field design that avoids demand characteristics often does so by giving up informed consent.
- Vulnerability to Misuse: A large project that re-ran 100 psychology studies found only about a third to a half of the original results held up (Open Science Collaboration, 2015). Flexible analysis and small samples can make a weak effect look real.
Contemporary Research
How Widespread Is the Replication Problem?
The Open Science Collaboration (2015) re-ran 100 published psychology studies. Only 36% of the replications reached statistical significance, and their effects averaged about half the original size.
The problem reaches beyond psychology.
Camerer et al. (2018) replicated 21 social science experiments published in Nature and Science between 2010 and 2015. About 62% replicated, again with smaller effects than the originals.
Why Do Findings Fail to Replicate?
Simmons, Nelson, and Simonsohn (2011) showed why so many findings failed to replicate. They used simulations to reveal a problem. Ordinary choices, such as which measures to report or when to stop collecting data, can make a false effect look significant.
John, Loewenstein, and Prelec (2012) surveyed over 2,000 psychologists using a method designed to encourage honest answers. A striking number admitted to practices like selective reporting and stopping data collection early once a result looked significant.
Do Preregistration and Registered Reports Help?
The field responded with preregistration.
Nosek, Ebersole, DeHaven, and Mellor (2018) describe how researchers now publicly register their hypotheses and analysis plan before collecting data.
This separates a genuine prediction from a pattern spotted after the fact, and reviewers can check the two match. But does registering in advance change what gets published?
Scheel, Schijen, and Lakens (2021) tested this directly. In registered reports, peer review and the decision to publish happen before the results are known. The researchers compared 71 registered reports with a random sample of 152 standard hypothesis-testing articles in psychology.
Only 44% of the registered reports supported their first hypothesis, against 96% of the standard articles. The gap was large. The authors suggested that reduced publication bias and less inflation of false positives may explain the gap.
References
Banerjee, A. V., & Duflo, E. (2009). The experimental approach to development economics. Annual Review of Economics, 1, 151–178. https://doi.org/10.1146/annurev.economics.050708.143235
Camerer, C. F., Dreber, A., Holzmeister, F., Ho, T.-H., Huber, J., Johannesson, M., Kirchler, M., Nave, G., Nosek, B. A., Pfeiffer, T., Altmejd, A., Buttrick, N., Chan, T., Chen, Y., Forsell, E., Gampa, A., Heikensten, E., Hummer, L., Imai, T., … Wu, H. (2018). Evaluating the replicability of social science experiments in Nature and Science between 2010 and 2015. Nature Human Behaviour, 2(9), 637–644. https://doi.org/10.1038/s41562-018-0399-z
Fitts, P. M. (1954). The information capacity of the human motor system in controlling the amplitude of movement. Journal of Experimental Psychology, 47(6), 381–391. https://doi.org/10.1037/h0055392
Goldschmied, N., Sheptock, M., Kim, K., & Galily, Y. (2017). Appraising Loftus and Palmer (1974) post-event information versus concurrent commentary in the context of sport. Quarterly Journal of Experimental Psychology, 70(11), 2347–2356. https://doi.org/10.1080/17470218.2016.1237980
Gonzalez-Franco, M., Slater, M., Birney, M. E., Swapp, D., Haslam, S. A., & Reicher, S. D. (2018). Participant concerns for the Learner in a virtual reality replication of the Milgram obedience study. PLOS ONE, 13(12), e0209704. https://doi.org/10.1371/journal.pone.0209704
Hodges, J., & Tizard, B. (1989). Social and family relationships of ex-institutional adolescents. Journal of Child Psychology and Psychiatry, 30(1), 77–97. https://doi.org/10.1111/j.1469-7610.1989.tb00770.x
Hofling, C. K., Brotzman, E., Dalrymple, S., Graves, N., & Pierce, C. M. (1966). An experimental study in nurse-physician relationships. Journal of Nervous and Mental Disease, 143(2), 171–180.
John, L. K., Loewenstein, G., & Prelec, D. (2012). Measuring the prevalence of questionable research practices with incentives for truth telling. Psychological Science, 23(5), 524–532.
Kohavi, R., Longbotham, R., Sommerfield, D., & Henne, R. M. (2009). Controlled experiments on the web: Survey and practical guide. Data Mining and Knowledge Discovery, 18(1), 140–181. https://doi.org/10.1007/s10618-008-0114-1
Loftus, E. F., & Palmer, J. C. (1974). Reconstruction of automobile destruction: An example of the interaction between language and memory. Journal of Verbal Learning and Verbal Behavior, 13(5), 585–589.
Medical Research Council. (1948). Streptomycin treatment of pulmonary tuberculosis. British Medical Journal, 2(4582), 769–782. https://doi.org/10.1136/bmj.2.4582.769
Milgram, S. (1963). Behavioral study of obedience. Journal of Abnormal and Social Psychology, 67(4), 371–378.
Nosek, B. A., Ebersole, C. R., DeHaven, A. C., & Mellor, D. T. (2018). The preregistration revolution. Proceedings of the National Academy of Sciences, 115(11), 2600–2606.
Open Science Collaboration. (2015). Estimating the reproducibility of psychological science. Science, 349(6251), aac4716.
Orne, M. T. (1962). On the social psychology of the psychological experiment: With particular reference to demand characteristics and their implications. American Psychologist, 17(11), 776–783.
Orne, M. T., & Holland, C. H. (1968). On the ecological validity of laboratory deceptions. International Journal of Psychiatry, 6(4), 282–293.
Roediger, H. L., III, & Karpicke, J. D. (2006). Test-enhanced learning: Taking memory tests improves long-term retention. Psychological Science, 17(3), 249–255. https://doi.org/10.1111/j.1467-9280.2006.01693.x
Rosenthal, R., & Fode, K. L. (1963). The effect of experimenter bias on the performance of the albino rat. Behavioral Science, 8, 183–189.
Rosenthal, R., & Jacobson, L. (1968). Pygmalion in the classroom: Teacher expectation and pupils’ intellectual development. Holt, Rinehart & Winston.
Scheel, A. M., Schijen, M. R. M. J., & Lakens, D. (2021). An excess of positive results: Comparing the standard psychology literature with registered reports. Advances in Methods and Practices in Psychological Science, 4(2). https://doi.org/10.1177/25152459211007467
Simmons, J. P., Nelson, L. D., & Simonsohn, U. (2011). False-positive psychology: Undisclosed flexibility in data collection and analysis allows presenting anything as significant. Psychological Science, 22(11), 1359–1366.
Williams, T. M. (Ed.). (1986). The impact of television: A natural experiment in three communities. Academic Press.