A z-score is a statistical measure that describes the position of a raw score in terms of its distance from the mean, measured in standard deviation units. A positive z-score indicates that the value lies above the mean, while a negative z-score indicates that the value lies below the mean.
It is also known as a standard score because it allows scores on different variables to be compared by standardizing the distribution.
A standard normal distribution (SND) is a normal distribution with a fixed mean and spread. As Figure 1 shows, its mean is 0 and its standard deviation (SD) is 1.

Why Are Z-Scores Important?
It is useful to standardize the values (raw scores) of a normal distribution by converting them into z-scores because:
- Probability estimation: Z-scores can be used to estimate the probability of a particular data point occurring within a normal distribution. By converting z-scores to percentiles or using a standard normal distribution table, you can determine the likelihood of a value being above or below a certain threshold.
- Hypothesis testing: Compare a sample statistic’s z-score with critical values to decide whether to reject or fail to reject the null hypothesis, the claim of no difference or effect. Failing to reject does not prove it true.
- Comparing datasets: Z-scores allow you to compare data points from different datasets by standardizing the values. This is useful when the datasets have different scales or units.
- Identifying outliers: Z-scores help identify outliers, which are data points significantly different from the rest of the dataset. Typically, data points with z-scores greater than 3 or less than -3 are considered potential outliers and may warrant further investigation.
Z-Scores in Psychological Testing
Many psychological tests report scores on rescaled z-scales. Each is a linear transformation of the z-score, chosen to avoid negative numbers and decimals.
- IQ-style scores: 100 + 15z. A score of 130 is z = +2, the 97.7th percentile.
- T-scores: 50 + 10z. These are not the same as the t statistic from a t-test.
- Admission-test scores: 500 + 100z in an older convention.
- Wechsler subtests: Scaled to a mean of 10 and a standard deviation of 3.
A percentile rank is the cumulative area written as a percentage. It is not the percentage of items answered correctly. A person can answer 55% of items correctly and still sit at the 95th percentile on a hard test.
Z-scores also put different measures side by side. A student scores 118 on a verbal test (mean 100, standard deviation 15). The same student scores 62 on a memory test (mean 50, standard deviation 8).
The z-scores are +1.20 and +1.50, about the 88th and 93rd percentiles. The memory score is stronger. That holds even though 62 is the smaller number.
Clinicians use the same logic to judge whether a client’s change exceeds measurement error. Jacobson and Truax (1991) proposed a reliable change index: the change score divided by the standard error of the difference between two scores.
A value beyond ±1.96 is unlikely to reflect measurement error alone at the 0.05 level. Such a change is called reliable.
On an anxiety scale with a baseline standard deviation of 7.0 and a reliability of 0.88, a 9-point improvement gives an index of 2.62. That counts as reliable. A 5-point improvement gives 1.46 and does not.
How To Calculate
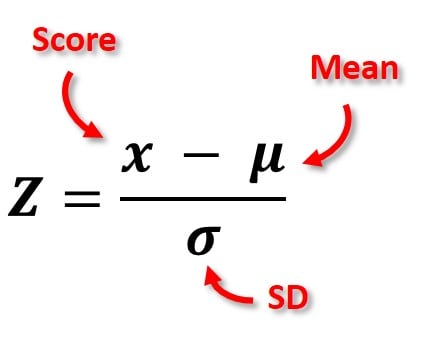
The formula for calculating a z-score is z = (x-μ)/σ, where x is the raw score, μ is the population mean, and σ is the population standard deviation.
As the formula shows, the z-score is simply the raw score minus the population mean, divided by the population standard deviation.
The population mean and standard deviation are usually unknown. In that case, calculate the standard score from the sample mean (x̄) and sample standard deviation (s), which estimate the population values.
To calculate a z-score, follow these steps:
- Identify the individual score (x) you want to convert to a z-score.
- Determine the mean (μ or mu) of the dataset. The mean is the average of all the scores.
- Calculate the standard deviation (σ or sigma) of the dataset. The standard deviation measures how spread out the scores are from the mean.
- Subtract the mean (μ) from the individual score (x). This will give you the difference between the score and the mean.
- Divide the difference you calculated in step 4 by the standard deviation (σ). The result is the z-score.
A set of z-scores always has a mean of exactly 0 and a standard deviation of exactly 1, whatever the raw scores were. Subtracting the mean centers the scores, and dividing by the standard deviation rescales their spread.
The shape does not change. A bell-shaped distribution stays bell-shaped, and a skewed one stays skewed. Standardizing changes the unit of measurement, not the distribution.
Statistical software usually divides by N − 1 when it standardizes a sample. The population formula divides by N instead, so the two choices give slightly different z-scores. State which one you used.
Interpretation
The value of the z-score tells you how many standard deviations you are away from the mean. A larger absolute value indicates a greater distance from the mean.
- Positive z-score: If a z-score is positive, it indicates that the data point is above the mean. For example, a z-score of 1.5 means the data point is 1.5 standard deviations above the mean.
- Negative z-score: If a z-score is negative, it indicates that the data point is below the mean. For example, a z-score of -2 means the data point is 2 standard deviations below the mean.
- Zero z-score: A z-score of zero indicates that the data point is equal to the mean.
Another way to interpret z-scores is by creating a standard normal distribution, also known as the z-score distribution, or probability distribution (see Fig. 3).
Probability Estimation
Z-score probabilities assume the original scores are roughly normally distributed. Once converted to z-scores, they have a mean of 0 and a standard deviation of 1, so standard normal tables or calculators can give probabilities.
The z-score tells us how many standard deviations a data point is from the mean.
Once we know the z-score, we can estimate the probability of a data point falling within a specific range or being above or below a certain value.
In a standard normal distribution, there’s a handy rule called the empirical rule, or the 68-95-99.7 rule. This rule states that:
- Approximately 68% of the data falls within one standard deviation of the mean (z-scores between -1 and 1).
- Around 95% of the data falls within two standard deviations of the mean (z-scores between -2 and 2).
- Nearly 99.7% of the data falls within three standard deviations of the mean (z-scores between -3 and 3).
Figure 3 shows the proportion of a standard normal distribution in percentages. There is a 95% probability of randomly selecting a score between -1.96 and +1.96 standard deviations from the mean.
The rule’s round numbers are approximations. Computed exactly, the shares within 1, 2 and 3 standard deviations are 0.6827, 0.9545 and 0.9973. The z-score that encloses exactly 95% is ±1.96, so “two standard deviations” is a convenient shortcut.
Probability here always means area. For a continuous measure, the chance of any single value is zero, so questions concern ranges.
| z-score | Area to the left | Where the score sits |
|---|---|---|
| −3 | 0.0013 | Lower than about 99.9% of scores |
| −2 | 0.0228 | 2.3rd percentile |
| −1 | 0.1587 | 16th percentile |
| 0 | 0.5000 | The mean and median, 50th percentile |
| +1 | 0.8413 | 84th percentile |
| +2 | 0.9772 | 97.7th percentile |
| +3 | 0.9987 | Higher than about 99.9% of scores |
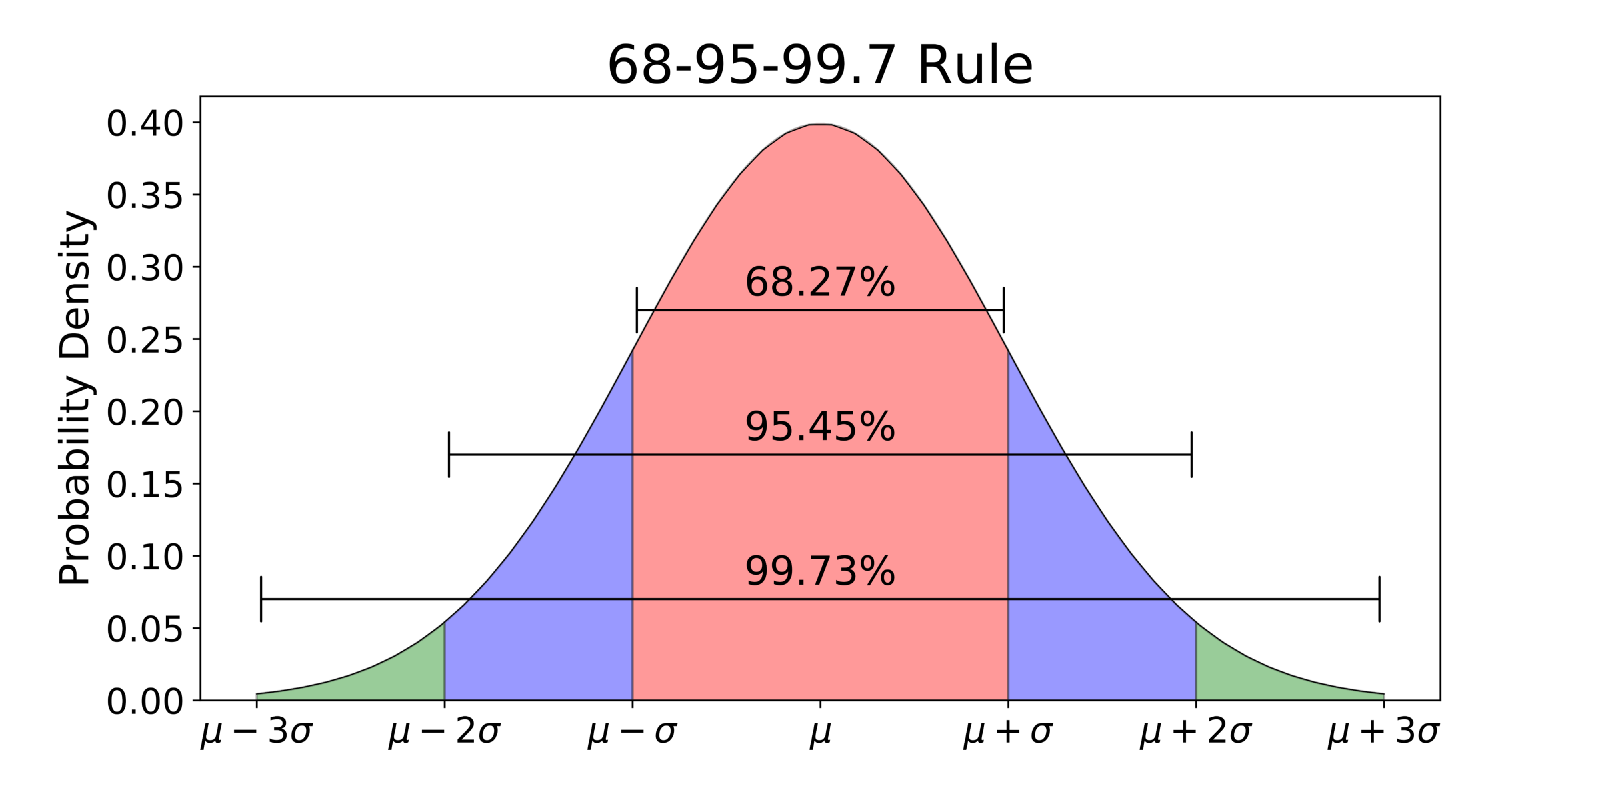
Using the standard normal distribution, researchers can calculate the probability of randomly obtaining a score from the sample. For example, there’s a 68% chance of randomly selecting a score between -1 and +1 standard deviations from the mean.
Hypothesis Testing
Using a z-score table lets you quickly determine the probability associated with a specific value in a dataset, helping you make decisions and draw conclusions based on your data.
- If you have a one-tailed test, you will look for the area to the left (for a left-tailed test) or right (for a right-tailed test) of your z-score.
- If you have a two-tailed test, you will look for the area in both tails combined.
The significance level (α) is the probability threshold for rejecting the null hypothesis. Common significance levels are 0.01, 0.05, and 0.10.
The critical values are the z-scores that correspond to the chosen significance level. These values can be found using a standard normal distribution table or calculator.
The table below lists the most common critical values. An observed z-score beyond the critical value is statistically significant at that level.
| Significance level (α) | Two-tailed critical value | One-tailed critical value |
|---|---|---|
| 0.10 | ±1.645 | 1.282 |
| 0.05 | ±1.960 | 1.645 |
| 0.01 | ±2.576 | 2.326 |
| 0.001 | ±3.291 | 3.090 |
These cut-offs are conventions, not laws of nature. Cowles and Davis (1982) traced the 0.05 level to early twentieth-century statements about when a deviation was too large to blame on chance. Fisher later restated those conventions.
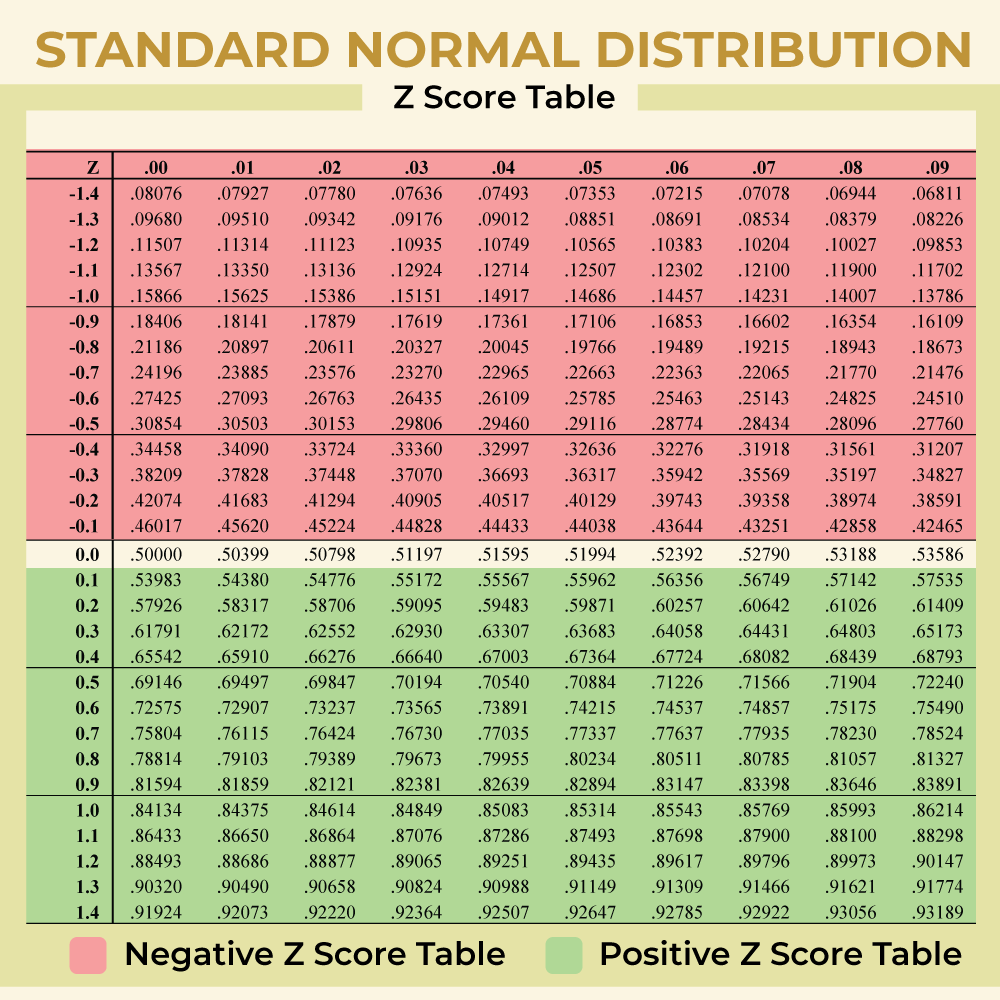
A Z-score table shows the percentage of values (usually a decimal figure) to the left of a given Z-score on a standard normal distribution.
Check Which Layout Your Z-Table Uses
A z-table (standard normal table) is a printed or on-screen grid of areas under the standard normal curve, indexed by z-score. Z-tables are not all the same, and reading the wrong layout gives an answer that looks plausible but is wrong. Three layouts are common.
- Cumulative table: Each entry is the area to the left of z. The entry for z = 0 is 0.5000, and entries rise toward 1.
- Mean-to-z table: Each entry is the area between the mean and z. The entry for z = 0 is 0.0000, and entries rise toward 0.5.
- Tail table: Each entry is the area beyond z in one tail. The entry for z = 0 is 0.5000, and entries fall toward 0.
To identify an unfamiliar table, look up z = 1.00. A cumulative table gives 0.8413, a mean-to-z table gives 0.3413, and a tail table gives 0.1587. Looking up z = 0 is not enough, because cumulative and tail tables both give 0.5000 there.
The steps below assume a cumulative table, the most common layout and the one statistical software uses.
1. Identify the parts of the z-score:
- Round your z-score to two decimal places, because z-tables print two decimals. A z-score of 1.0934 becomes 1.09.
- Split it into a row label and a column label. The whole number plus the first decimal gives the row (1.2 for z = 1.24), and the second decimal gives the column (0.04).
- Rounding to one decimal place can change the answer. In a cumulative table, z = 1.09 gives 0.8621 but z = 1.1 gives 0.8643, a gap that can matter near a significance threshold.
2. Find the corresponding probability in the z-score table:
- Z-score tables print the row labels (the whole number and first decimal) down the left column and the column labels (the second decimal) across the top row
- Locate the row for your z-score in the leftmost column (1.2 for z = 1.24)
- Move across the row until you reach the column that matches the second decimal (0.04)
- The value where the row and column meet is the area under the curve (the proportion of scores in that stretch of the distribution) associated with your z-score
- In a cumulative table, z = 1.24 gives 0.8925, so about 89% of scores fall below it
3. Interpret the probability:
- For a left-tailed test, the probability you found in the table is your p-value
- For a right-tailed test, subtract the probability you found from 1 to get your p-value
- For a two-tailed test, double the tail area beyond the absolute value of your z-score. For a positive z-score, that is 2 × (1 − table value). For a negative z-score, it is 2 × the table value
- Compare the probability to your chosen alpha level (0.05 or 0.01). If the probability is less than the alpha level, the result is considered statistically significant
A result is statistically significant when its p-value falls below the significance level chosen in advance, usually 0.05. The p-value is the probability of a result at least this extreme if the null hypothesis, and every other assumption behind the test, were true.
Even academic psychologists misread it (Badenes-Ribera et al., 2016). The p-value is not the probability that the null hypothesis is true. Nor is it the probability that chance alone produced the result, or that the effect is real (Greenland et al., 2016; Wasserstein & Lazar, 2016).
A small p-value says the data sit awkwardly with the null model. It does not say the effect is large. Significance also depends on sample size.
Worked Example: A Two-Tailed Z-Test
A wellbeing scale has a population mean of 50 and a standard deviation of 10. Twenty-five participants complete a four-week program and score a mean of 54.5. Does this group differ from the population mean?
- State the hypotheses: H0 is μ = 50 and H1 is μ ≠ 50. Set α = 0.05 before seeing the data.
- Calculate the standard error (the typical gap between a sample mean and the population mean): 10 / √25 = 2.0. Then z = (54.5 − 50) / 2.0 = +2.25.
- Look up the area. The area to the left of 2.25 is 0.9878, so the right tail is 0.0122.
- Double the tail for a two-tailed test: p = 2 × 0.0122 = 0.0244.
- Decide. The z of 2.25 is beyond the critical value of ±1.96, so reject the null hypothesis.
At α = 0.01 the same data fail to reject the null hypothesis, because 2.25 does not reach ±2.576. A result is only significant relative to a threshold fixed in advance.
Notice the divisor.
A sample mean is divided by the standard error, not by the standard deviation of individual scores. Dividing by 10 would give z = 0.45 and wrongly suggest nothing unusual.
Report an effect size as well. Here d = (54.5 − 50) / 10 = 0.45, a small-to-medium effect by the usual benchmarks. The same 4.5-point difference in 100 participants gives z = 4.5 and a tiny p-value, yet d is still 0.45.
Common Mistakes When Using Z-Scores and Z-Tables
Most errors come from the wrong tail, the wrong layout or the wrong divisor. Sketch the bell curve and shade the area the question asks about before you touch the table.
- Wrong tail: A cumulative table always gives the area to the left. For “the proportion who scored higher,” subtract the entry from 1.
- Wrong layout: A mean-to-z table read as cumulative is off by exactly 0.5. Check with z = 1.00 first.
- Negative z-scores: There is no negative area. Look up the absolute value, then decide whether you need the entry or 1 minus it.
- Two-tailed p-values: Double the single tail beyond the absolute value of z. Doubling the cumulative entry of a positive z gives a value above 1.
- Z as a probability: A z-score is a position on the axis, not a probability. The probability is the area linked to that position.
- Wrong divisor: For a sample mean, divide by the standard error (σ / √n), not by the standard deviation σ.
- “Accepting” the null: A p-value above α means you fail to reject the null hypothesis. It does not show the null hypothesis is true.
p-value from z-score calculator
P-value:
Conclusion:
Practice Problems for Z-Scores
Calculate the z-scores for the following:
Sample Questions
- Scores on a psychological well-being scale range from 1 to 10, with an average score of 6 and a standard deviation of 2. What is the z-score for a person who scored 4?
- On a measure of anxiety, a group of participants show a mean score of 35 with a standard deviation of 5. What is the z-score corresponding to a score of 30?
- A depression inventory has an average score of 50 with a standard deviation of 10. What is the z-score corresponding to a score of 70?
- In a study on sleep, participants report an average of 7 hours of sleep per night, with a standard deviation of 1 hour. What is the z-score for a person reporting 5 hours of sleep?
- On a memory test, the average score is 100, with a standard deviation of 15. What is the z-score corresponding to a score of 85?
- A happiness scale has an average score of 75 with a standard deviation of 10. What is the z-score corresponding to a score of 95?
- An intelligence test has a mean score of 100 with a standard deviation of 15. What is the z-score that corresponds to a score of 130?
Answers for Sample Questions
Double-check your answers with these solutions. Remember, for each problem, you subtract the average from your value, then divide by how much values typically vary (the standard deviation).
- Z-score = (4 – 6)/2 = -1
- Z-score = (30 – 35)/5 = -1
- Z-score = (70 – 50)/10 = 2
- Z-score = (5 – 7)/1 = -2
- Z-score = (85 – 100)/15 = -1
- Z-score = (95 – 75)/10 = 2
- Z-score = (130 – 100)/15 = 2
Calculating a Raw Score
Sometimes, we know a z-score and want to find the corresponding raw score. The formula for calculating a z-score in a sample into a raw score is given below:
X = (z)(SD) + mean
As the formula shows, the z-score and standard deviation are multiplied together, and this figure is added to the mean.
Check your answer makes sense. A negative z-score must give a raw score below the mean. A positive z-score must give a raw score above it.
The same formula turns a percentile into a raw score. First find the z-score for that percentile, then convert it. This is how cut scores are set.
For example, on an IQ-style scale (mean 100, standard deviation 15), the top 10% begins at the 90th percentile. That is z = 1.28, so X = 100 + 1.28 × 15 = 119.2.
Calculating a Z-Score using Excel
To calculate the z-score of a specific value, x, work through these steps. The examples assume your sample scores sit in cells A1 to A20.
- Mean: Type =AVERAGE(A1:A20) to return the average of those numbers.
- Standard deviation: Type =STDEV.S(A1:A20) to return the sample standard deviation of those numbers.
- Z-score: In an empty cell, type = (x – mean) / [standard deviation].
- Cell references: Instead of typing the mean and SD, point to the cells that hold them, for example = (A12 – B1) / C1.
- Left-tail probability: For a smaller z-score (the area under the curve to the left of x), type =NORM.S.DIST(z, TRUE) with your z-score in place of z. The older =NORMSDIST(z) also works.
- Right-tail probability: For a larger z-score (the area to the right of x), type =1 – NORM.S.DIST(z, TRUE).
- Two-tailed p-value: Type =2 * (1 – NORM.S.DIST(ABS(z), TRUE)).
Always include TRUE. Without it, Excel returns the height of the curve, which is not a probability.
Frequently Asked Questions
Can z-scores be used with any type of data, regardless of distribution?
Z-scores are commonly used to standardize and compare data across different distributions. They are most appropriate for data that follows a roughly symmetric and bell-shaped distribution.
However, they can still provide useful insights for other types of data, as long as certain assumptions are met. Yet, for highly skewed or non-normal distributions, alternative methods may be more appropriate.
It’s important to consider the characteristics of the data and the goals of the analysis when determining whether z-scores are suitable or if other approaches should be considered.
How can understanding z-scores contribute to better research and statistical analysis in psychology?
Understanding z-scores enhances research and statistical analysis in psychology. Z-scores standardize data for meaningful comparisons, identify outliers, and assess likelihood.
They aid in interpreting practical significance, applying statistical tests, and making accurate conclusions. Z-scores provide a common metric, facilitating communication of findings.
By using z-scores, researchers improve rigor, objectivity, and clarity in their work, leading to better understanding and knowledge in psychology.
Can a z-score be used to determine the likelihood of an event occurring?
No, a z-score itself cannot directly determine the likelihood of an event occurring. However, it provides information about the relative position of a data point within a distribution.
By converting data to z-scores, researchers can assess how unusual or extreme a value is compared to the rest of the distribution. This can help estimate the probability or likelihood of obtaining a particular score or more extreme values.
So, while z-scores provide insights into the relative rarity of an event, they do not directly determine the likelihood of the event occurring on their own.
Critical Evaluation
The arithmetic of a z-score is simple and reliable. The weaknesses lie in how it is used. Four stand out.
The Normal Distribution Assumption
The z-score formula works on any distribution. The z-table does not. Reading a percentile or p-value from it treats the tails of your data as if they were the tails of a normal distribution.
Standardizing never changes a distribution’s shape, so a skewed variable stays skewed. Real psychological measures are often far from normal, as Micceri (1989) showed.
- Aim: To investigate the distributional characteristics of large-sample achievement and psychometric measures, the kind of data that standard scores and norm tables are built on.
- Method: Micceri examined 440 large-sample distributions of achievement and psychometric measures. He tested each for departure from normality at the 0.01 significance level.
- Results: All 440 were significantly non-normal. Many showed heavy or light tails, strong asymmetry, multiple peaks or digit preferences.
- Conclusion: Normality-based assumptions looked unsafe for this kind of data, and the robustness literature needed re-evaluating.
With very large samples a normality test detects trivial departures, so the shapes found matter more than the significance count. The warning is sharpest in the tails, where percentile conversions are most sensitive. Percentiles counted directly from the ranked scores need no assumption about shape.
Outliers and Small Samples
A z above 3 is a prompt, not proof. Even in perfectly normal data, about 2.7 scores per 1,000 lie beyond ±3.
Extreme scores also distort the mean and standard deviation used to judge them. One outlier can inflate the standard deviation enough to hide its own z-score. This is called masking. Leys et al. (2013) therefore recommended the median and the median absolute deviation instead.
Small samples add a hard ceiling. With n scores and the sample standard deviation, no z-score can exceed (n − 1) / √n in size. The ceiling is 1.79 for five scores, 2.85 for ten and 4.25 for twenty.
In nine zeros and one 100, the extreme score has a z of 2.85. It never reaches a cut-off of three.
Estimated Standard Deviations
The z-table assumes the standard deviation is known. When it is estimated from a small sample, the normal curve understates the uncertainty. Student (1908) worked out the correction.
- Aim: To find when normal tables can judge the significance of a sample mean, and to supply alternative tables for samples too small for the normal curve.
- Method: Student derived the sampling distribution for samples from a normal population. He then wrote the heights of 3,000 criminals on cards, shuffled them and drew 750 samples of four to test the curve.
- Results: A sample’s mean and standard deviation are uncorrelated. The derived curve matched the 750 samples well enough, even though the population was not strictly normal.
- Conclusion: For small samples, normal tables understate uncertainty and different tables are needed. This became the t-distribution.
Using z-table areas for a small-sample statistic therefore gives p-values that are too small.
In the worked example above, suppose the standard deviation of 10 had been estimated from the 25 scores. The two-tailed p-value would then rise from 0.0244 to 0.034.
Reference Groups and Norms
A z-score only says where someone stands compared with a specific group. Change the reference group and the same raw score earns a different z-score. This is why norm groups matter.
Behavioral-science samples are drawn heavily from Western, educated, industrialized, rich and democratic societies, which prove to be unusual outliers across many measured domains (Henrich et al., 2010). A norm group built from such samples inherits that narrowness.
Someone assessed against a group that does not resemble them is placed on the wrong ruler. Norms also drift over time, as the Flynn effect shows.
This matters when cut-offs feed decisions about people. A cut-off such as an IQ about two standard deviations below the mean turns a gradual difference into a sharp category.
Contemporary Research
Recent meta-research asks whether the normal curve is the right ruler for real psychological data. It consistently answers: often not.
An analysis of 693 small-sample distributions of cognitive and other psychological measures found only 5.5% close to normal values of skewness and kurtosis (Blanca et al., 2013). Larger collections point the same way.
These are descriptive studies. They show how common non-normality is, not how often it changes a conclusion.
How Common Is Non-Normal Data?
- Aim: To measure how common nonnormality is in univariate and multivariate data from psychological and educational research.
- Method: Cain, Zhang and Yuan examined 1,567 univariate and 254 multivariate distributions supplied by authors of articles in two journals. A simulation then used typical skewness and kurtosis values to estimate the effect on error rates.
- Results: 74% of univariate and 68% of multivariate distributions deviated from normality. Type I error rates reached 17% in a t-test and 30% in a factor analysis under some conditions.
- Conclusion: Skewness and kurtosis should be reported routinely alongside means and variances.
Cain et al. (2017) used real data and a simulation anchored in observed values. The data came from authors in two journals, so they are not a random draw of all psychology.
The simulations concern inferential tests, not z-table percentiles.
Modelled Norms Instead of Table Lookups
Test norms are conventionally built by ranking scores within age bands and converting them to standard scores. Regression-based continuous norming instead models raw scores as a smooth function of percentile and age.
Lenhard and Lenhard (2021) compared the two in a simulation. They cross-validated the norms on a representative sample of 840,000 cases across 90,000 repetitions.
Both approaches improved with sample size. Modelled norms reached optimal results with much smaller samples. A simulation is weaker evidence than clinical data, but it knows the true answer.
Do Researchers Misread P-Values?
- Aim: To find how widespread p-value misreadings are among academic psychologists in Italy and Chile.
- Method: An online survey in March to May 2015 invited 2,321 academic psychologists, and 164 responded (7.07%). Each saw a result of p = .001 and ticked the true statements among ten, eight of them false.
- Results: 32.9% ticked that the null hypothesis had been shown false, and 23.8% that its probability had been determined. In all, 61.6% endorsed at least one inverse-probability error.
- Conclusion: Misinterpretation persists among academic psychologists, methodologists included, and better statistical education is needed.
This is a convenience sample with a 7% response rate. Respondents may have been more statistically knowledgeable than non-respondents, so the figures may understate the problem.
The survey also measures quiz answers, not how people interpret p-values in their own analyses. Expert guidance already warns against these misreadings (Greenland et al., 2016; Wasserstein & Lazar, 2016). That guidance is a statement of consensus, not new data.
Together, the studies point one way. A correct table lookup can still mislead, either because the data are not normal or because the p-value is misread.
Key Takeaways
- Z-Score: A z-score is (raw score − mean) / standard deviation. It states how many standard deviations a score lies above (positive) or below (negative) the mean.
- Comparison: Standardizing puts scores from different scales on one ruler. You can then compare them and combine them into composites.
- Empirical Rule: In a normal distribution, about 68%, 95% and 99.7% of scores fall within 1, 2 and 3 standard deviations of the mean.
- Z-Table Layouts: Cumulative, mean-to-z and tail tables differ. Look up z = 1.00 to tell which you have: 0.8413, 0.3413 or 0.1587.
- P-Values: For a two-tailed test, double the single tail beyond the absolute value of z. A p-value is not the probability that the null hypothesis is true.
- Normality: The formula works on any data. Percentiles and p-values read from a z-table assume a roughly normal distribution, which real psychological data often lack.
- Outliers: A z above 3 is a prompt to investigate, not proof of an outlier. In samples of 10 or fewer, a z of 3 cannot occur.
References
Badenes-Ribera, L., Frias-Navarro, D., Iotti, B., Bonilla-Campos, A., & Longobardi, C. (2016). Misconceptions of the p-value among Chilean and Italian academic psychologists. Frontiers in Psychology, 7, Article 1247. https://doi.org/10.3389/fpsyg.2016.01247
Blanca, M. J., Arnau, J., López-Montiel, D., Bono, R., & Bendayan, R. (2013). Skewness and kurtosis in real data samples. Methodology, 9(2), 78–84. https://doi.org/10.1027/1614-2241/a000057
Cain, M. K., Zhang, Z., & Yuan, K.-H. (2017). Univariate and multivariate skewness and kurtosis for measuring nonnormality: Prevalence, influence and estimation. Behavior Research Methods, 49(5), 1716–1735. https://doi.org/10.3758/s13428-016-0814-1
Cowles, M., & Davis, C. (1982). On the origins of the .05 level of statistical significance. American Psychologist, 37(5), 553–558. https://doi.org/10.1037/0003-066X.37.5.553
Greenland, S., Senn, S. J., Rothman, K. J., Carlin, J. B., Poole, C., Goodman, S. N., & Altman, D. G. (2016). Statistical tests, P values, confidence intervals, and power: A guide to misinterpretations. European Journal of Epidemiology, 31(4), 337–350. https://doi.org/10.1007/s10654-016-0149-3
Henrich, J., Heine, S. J., & Norenzayan, A. (2010). The weirdest people in the world? Behavioral and Brain Sciences, 33(2–3), 61–83. https://doi.org/10.1017/S0140525X0999152X
Jacobson, N. S., & Truax, P. (1991). Clinical significance: A statistical approach to defining meaningful change in psychotherapy research. Journal of Consulting and Clinical Psychology, 59(1), 12–19. https://doi.org/10.1037/0022-006X.59.1.12
Lenhard, W., & Lenhard, A. (2021). Improvement of norm score quality via regression-based continuous norming. Educational and Psychological Measurement, 81(2), 229–261. https://doi.org/10.1177/0013164420928457
Leys, C., Ley, C., Klein, O., Bernard, P., & Licata, L. (2013). Detecting outliers: Do not use standard deviation around the mean, use absolute deviation around the median. Journal of Experimental Social Psychology, 49(4), 764–766. https://doi.org/10.1016/j.jesp.2013.03.013
Micceri, T. (1989). The unicorn, the normal curve, and other improbable creatures. Psychological Bulletin, 105(1), 156–166. https://doi.org/10.1037/0033-2909.105.1.156
Student. (1908). The probable error of a mean. Biometrika, 6(1), 1–25. https://doi.org/10.2307/2331554
Wasserstein, R. L., & Lazar, N. A. (2016). The ASA statement on p-values: Context, process, and purpose. The American Statistician, 70(2), 129–133. https://doi.org/10.1080/00031305.2016.1154108
Further Information
- How to Use a Z-Table (Standard Normal Table) to Calculate the Percentage of Scores Above or Below the Z-Score
- Z-Score Table (for positive or negative scores)
- Statistics for Psychology Book Download