A Z-score table, also called a standard normal table or z-score chart, shows the proportion of values that fall below a given Z-score on a standard normal distribution (SND). The proportion is the area to the left of the Z-score, usually printed as a decimal.

Positive and Negative Z-Score Tables
-
Positive Z-score Table: Used for Z-scores above the mean. It gives the percentage or probability of values below a given positive Z-score.
-
Negative Z-score Table: Used for Z-scores below the mean. It gives the percentage or probability of values below a given negative Z-score.
Each type of table typically lists the whole number and tenth place of the Z-score down the rows (e.g., -3.3, -3.2, …, 3.2, 3.3). The hundredth place runs across the columns (e.g., 0.00, 0.01, …, 0.09).
A Z-score table can be used to determine if a score is statistically significant by providing a way to find the p-value associated with a given Z-score.
The p-value is the probability of obtaining a result at least as extreme as the one observed, assuming the null hypothesis is true.
How To Read Z-Score Table
Reading a Z-score table is straightforward once you understand the layout.
Z-tables come in three common layouts. The most common is the cumulative (“less than”) table, which gives the area to the left of the Z-score.
The other two give the area between the mean and the Z-score, or the area in the tail beyond it (a “more than” table). Check which layout you have before reading any entry.
A Z-score table shows the percentage of values (usually a decimal figure) to the left of a given Z-score on a standard normal distribution.
The total area under the curve is 1 (or 100%). The area over any stretch of the axis is the proportion of scores in that stretch. It is also the probability that a randomly chosen score falls there.
Probability means area, not height. For a continuous variable, the probability of landing on exactly one value is zero.
Questions are therefore about ranges, such as “at or above”, “between” or “at least as extreme as”.
The curve is also symmetrical around the mean. So the area to the left of −1.25 equals the area to the right of +1.25. This is why many printed tables list positive Z-scores only.
Steps for Reading a Z-Table
-
Look down the left column for the first part of your Z-score: the whole number and the first digit after the decimal point.
-
Look along the top row for the second part: the remaining decimal digit.
-
Read the value where the row and column intersect. It is the proportion of the data set that lies below your Z-score in a standard normal distribution.
Example: Reading a Z-Score of 1.09
First, look at the left side column of the z-table to find the value corresponding to one decimal place of the z-score. In this case, it is 1.0.
Then, we look up the remaining number across the table (on the top), which is 0.09 in our example.

The corresponding area is 0.8621. That means 86.21% of the standard normal distribution lies below (to the left of) the Z-score.
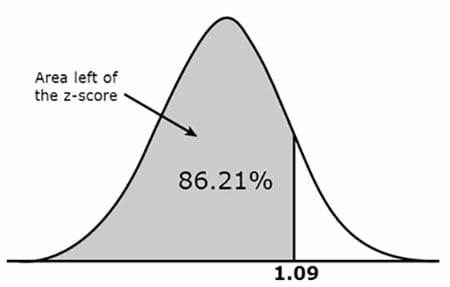
To find a two-tailed p-value, subtract this from 1 (which gives you 0.1379), then multiply by 2 (which gives you p = 0.2758).
The result is not statistically significant. The p-value is greater than the significance level of .05, which must be set before the test. So we fail to reject the null hypothesis.
Failing to reject the null hypothesis is not the same as showing that it is true. It means the data do not give enough evidence against it.
Which Z-Table Layout Do You Have?
Reading a table with the wrong rule gives an answer that looks plausible but is wrong. Three layouts are in common use:
- Cumulative table: Each entry is the area to the left of z. The entry for z = 0 is .5000, and entries rise towards 1.
- Mean-to-z table: Each entry is the area between 0 and z. The entry for z = 0 is .0000, and entries rise towards .5.
- Tail table: Each entry is the area beyond z. The entry for z = 0 is .5000, and entries fall towards 0.
The cumulative layout is the most common, and statistical software uses it. Older textbooks often print the mean-to-z layout.
To identify an unfamiliar table, look up z = 1.00. A cumulative table gives .8413, a mean-to-z table gives .3413, and a tail table gives .1587. Looking up z = 0 is not enough, because cumulative and tail tables both give .5000 there.
The table below shows the three layouts side by side. The last column is the two-tailed area (both tails combined), used for two-tailed p-values.
| z | Cumulative (left of z) | Mean to z | Tail (right of z) | Two-tailed (both tails) |
|---|---|---|---|---|
| 0.00 | .5000 | .0000 | .5000 | 1.0000 |
| 0.50 | .6915 | .1915 | .3085 | .6171 |
| 1.00 | .8413 | .3413 | .1587 | .3173 |
| 1.50 | .9332 | .4332 | .0668 | .1336 |
| 1.96 | .9750 | .4750 | .0250 | .0500 |
| 2.00 | .9772 | .4772 | .0228 | .0455 |
| 2.576 | .9950 | .4950 | .0050 | .0100 |
| 3.00 | .9987 | .4987 | .0013 | .0027 |
Right of a positive z-score
To find the area to the right of a positive z-score, begin by reading off the area in the standard normal distribution table.
The total area under the bell curve is 1 (equivalent to 100%). So subtract the area from the table from 1.00.
Take z = 1.09. The area to its left is .8621. So the area to its right is 1 − .8621 = .1379, or 13.79%.
Left of a negative z-score
If your table lists negative Z-scores, read the entry directly. If it lists positive Z-scores only, ignore the minus sign, look up the positive value, then subtract the table entry from 1.00.
For example, z = −1.09 has a left-hand area of 1 − .8621 = .1379. By symmetry, this equals the area to the right of z = +1.09.
Negative Z-scores leave under half the curve to their left. So the answer must be below .5.
Right of a negative z-score
If your table lists negative Z-scores, read the entry and subtract it from 1.00. If it lists positive Z-scores only, ignore the minus sign and read the entry directly. For z = −1.09, that gives .8621.
Because the curve is symmetrical, the area right of a negative Z-score equals the area left of its positive twin. A negative Z-score sits below the mean, so more than half the curve lies to its right. The answer must be above .5.
Finding the area between two z-scores
The area between two Z-scores is the larger cumulative area minus the smaller. This works for any combination of signs, because a cumulative table accumulates from the far left.
For example, the area between z = −0.50 and z = +1.00 is .8413 − .3085 = .5328, where .3085 is the area to the left of z = −0.50. About 53.3% of scores fall in that range.
With a positive-only table and two negative Z-scores, use the tails instead. First, find the area left of the lower Z-score. Then find the area right of the higher one. Add the two areas and subtract the sum from 1 (the total area under the SND).
For z = −2 and z = −1, the area is 1 − (.0228 + .8413) = .1359.
Converting Between Z-Table Layouts
Whichever layout your table uses, simple arithmetic gives the same areas. The total area is 1, and each side of the mean holds .5.
In the table below, A, B and C are the cumulative, mean-to-z and tail entries for the same positive Z-score.
| What you want | From a cumulative table (A) | From a mean-to-z table (B) | From a tail table (C) |
|---|---|---|---|
| Area to the left of a positive z | A | .5 + B | 1 − C |
| Area to the right of a positive z | 1 − A | .5 − B | C |
| Area to the left of a negative z (look up the positive value) | 1 − A | .5 − B | C |
| Area to the right of a negative z (look up the positive value) | A | .5 + B | 1 − C |
| Area between the mean and z | A − .5 | B | .5 − C |
| Area outside ±z (both tails) | 2 × (1 − A) | 1 − 2B | 2C |
Take z = 1.30 as a check. The cumulative entry is .9032, the mean-to-z entry is .4032, and the tail entry is .0968.
The area to the left is .9032, which equals .5 + .4032 and 1 − .0968. The area to the right is .0968, which equals 1 − .9032 and .5 − .4032.
Finding Areas in Excel and Other Software
Software removes the need to read a table, but the logic is identical. It also removes table rounding, so a computed p-value can differ from a table-based one in the fourth decimal place.
- Z-score in Excel:
=STANDARDIZE(x, mean, standard_dev). - Left-tail area in Excel:
=NORM.S.DIST(z, TRUE).TRUEasks for the cumulative area;FALSEreturns the height of the curve, which is not a probability. - Right-tail area in Excel:
=1-NORM.S.DIST(z, TRUE). - Two-tailed p in Excel:
=2*(1-NORM.S.DIST(ABS(z), TRUE)). - Z for a percentile in Excel:
=NORM.S.INV(probability). - Python (SciPy):
norm.cdf(z)for the left tail,norm.sf(z)for the right tail, andnorm.ppf(p)for the inverse. - R:
pnorm(z)for the left tail andqnorm(p)for the inverse.
Common Mistakes When Using a Z-Table
Most errors come from a handful of habits. Sketch the bell curve, mark the Z-score and shade the region the question asks about before touching the table. If the shaded region is more than half the curve, the answer must be above .5.
- Taking the wrong tail: A cumulative table always gives the area to the left. “The proportion who scored higher” needs 1 minus the entry for a positive Z-score.
- Mixing up layouts: Cumulative rules applied to a mean-to-z table give answers off by exactly .5. Test the layout with z = 1.00 first.
- Mishandling negative Z-scores: There is no negative area. Look up the absolute value in a positive-only table, then decide whether you need the entry or its complement.
- Doubling wrongly for two-tailed p: Find the single tail beyond the absolute value of z, then double it. Doubling the cumulative entry of a positive z gives values above 1.
- Rounding z too early: Look up z to two decimal places. Rounding 1.0934 to 1.1 instead of 1.09 changes .8621 to .8643, which can matter near a significance threshold.
- Treating z as a probability: A Z-score is a position on the axis, not a probability or a percentage. The probability comes from the area at that position.
Z-Table P-Values and Significance Tests
When a test statistic is a Z-score, its p-value is a tail area of the standard normal curve. A z-table turns the statistic into that area. You then compare the area with the significance level you chose in advance.
One-Tailed and Two-Tailed P-Values
Below, A(z) means the cumulative-table entry for z. The tail you use depends on the direction the hypothesis predicts:
- Right-tailed test: The hypothesis predicts a larger value, so p = 1 − A(z), the area to the right of z.
- Left-tailed test: The hypothesis predicts a smaller value, so p = A(z), the area to the left of z.
- Two-tailed test: The hypothesis predicts a difference in either direction, so p = 2 × (1 − A(|z|)).
The two-tailed rule is the one most often applied wrongly. The sign of z does not matter. Take the absolute value of z. Find the single tail beyond it, then double it.
For z = 2.17, the single tail is .0150 and the two-tailed p is .0300. For z = −1.84, the single tail is .0329 and the two-tailed p is .0658.
A two-tailed p cannot exceed 1.00. If doubling the cumulative entry for z = 2.17 gives 2 × .9850 = 1.97, something has gone wrong.
Choose between one and two tails before you look at the data. It is a design decision. Do not read it off the results.
Critical Values and Significance Levels
You can skip the p-value. Compare your Z-score with a critical value instead. This is the Z-score that cuts off the significance level (alpha) in the relevant tail or tails.
Critical values come from reading the table backwards. Find the area in the body of the table, then read off the matching row and column labels.
The 95th percentile is z = 1.645. The 97.5th is z = 1.960. If your Z-score lies beyond the critical value, the result is significant at that level.
| Significance level (α) | Two-tailed critical value | One-tailed critical value |
|---|---|---|
| .10 | ±1.645 | 1.282 |
| .05 | ±1.960 | 1.645 |
| .01 | ±2.576 | 2.326 |
| .001 | ±3.291 | 3.090 |
A two-tailed test needs a larger Z-score than a one-tailed test at the same alpha, because the rejection region is split between two tails. A Z-score of 1.80 is significant at .05 one-tailed but not two-tailed.
Worked Example: A Two-Tailed Test
A wellbeing scale has a reference mean of 50 and a standard deviation of 10. Twenty-five participants complete a four-week programme and have a mean score of 54.5. Does this group differ from the reference mean?
- Hypotheses: H0 is μ = 50 and H1 is μ ≠ 50 (two-tailed), with α = .05 fixed in advance.
- Z statistic: The standard error is 10 / √25 = 2.0, so z = (54.5 − 50) / 2.0 = +2.25.
- P-value: The area to the left is .9878, so the right tail is .0122 and the two-tailed p is .0244.
- Decision at .05: The critical value is ±1.96. Because 2.25 lies beyond it, we reject the null hypothesis.
- Decision at .01: The critical value is ±2.576, which 2.25 does not reach. The same data fail to reject the null hypothesis.
- Effect size: d = (54.5 − 50) / 10 = 0.45, a little below Cohen’s (1988) rough benchmark of 0.5 for a medium effect size.
The same data are significant at one threshold and not at another. That is why the threshold must be chosen before the data are seen.
The test assumes a random sample whose mean has an approximately normal sampling distribution, which the central limit theorem supports for large samples.
Individual Scores vs Sample Means
Two different quantities share the name Z-score. The same table serves both, but the divisor differs.
- Z-score for an individual: The deviation divided by the standard deviation of the scores. It shows where one person sits in a distribution.
- Z statistic for a sample mean: The deviation divided by the standard error, σ / √n. It shows how surprising a sample mean is if the null hypothesis is true.
Take an IQ-style test with a mean of 100 and a standard deviation of 15. A single student scoring 105 has z = (105 − 100) / 15 = +0.33. That is unremarkable.
A class mean is different. With 36 students averaging 105, the standard error is 15 / √36 = 2.5. So z = +2.00 and the two-tailed p is .0455.
Dividing by the standard deviation instead would give z = 0.33 and the false conclusion that the result is ordinary.
Limitations of the Z-Table
The z-score and z-table are among the most durable tools in statistics. Their weaknesses lie in how they are used, not in the arithmetic.
Real Data Are Often Not Normal
A z-table describes a data set only if that data set is approximately normal. Standardising does not change a distribution’s shape, so a skewed distribution stays skewed after conversion to Z-scores.
Real psychological data are often not normal. Two large collections show how often:
- Micceri (1989): All 440 large-sample achievement and psychometric distributions tested were significantly non-normal, with tails lighter or heavier than normal, strong asymmetry and multiple peaks.
- Blanca et al. (2013): Only 5.5% of 693 distributions of cognitive and other psychological measures were close to normal values of skewness and kurtosis.
The shapes Micceri found did not resemble the distributions used in most earlier robustness research.
Departures from normality matter far less for tests on sample means than for percentile readings of individual scores. So check percentiles against the real distribution.
A Skewed Example: Reaction Times
A small example shows the problem. Ten reaction times (in milliseconds) are 310, 320, 335, 340, 355, 360, 380, 410, 520 and 780. The mean is 411 and the standard deviation is 143. The median is only 357.5, a clear right skew.
The table compares normal-table percentiles with percentiles counted directly from the data.
| Reaction time | z | Percentile from the normal table | Percentile counted directly |
|---|---|---|---|
| 310 ms (fastest) | −0.71 | 24th | 5th |
| 410 ms | −0.01 | 50th | 75th |
| 520 ms | +0.76 | 78th | 85th |
| 780 ms (slowest) | +2.58 | 99.5th | 95th |
Direct counts use the mid-rank convention: the percentage of scores below a value plus half the percentage equal to it.
The normal table places the fastest participant at the 24th percentile when no one in the sample is faster. It puts a person at the 50th percentile when about three-quarters of the sample was faster.
The long tail inflates the mean and standard deviation. A percentile counted directly from the ranks does not depend on distribution shape, so it is the safer description for skewed data.
Small Samples: When z Is the Wrong Ruler
The z-table assumes the standard deviation is known. When it is estimated from a small sample, the normal curve understates the uncertainty. Student (1908) tackled this problem.
Student derived the sampling distribution of a sample mean’s distance from the population mean, divided by the sample’s standard deviation. He then tested it empirically.
He wrote the height and finger measurements of 3,000 criminals on cards, shuffled them, and treated each consecutive set of four as a sample. The curve fitted the resulting 750 samples well enough.
This work is the origin of the t-distribution. It is why a z-test needs a known standard deviation or a large sample.
Return to the wellbeing example. Suppose the standard deviation of 10 had been estimated from the 25 scores.
| Standard deviation of 10 | Reference curve | Two-tailed p | Critical value at .05 | Critical value at .01 |
|---|---|---|---|---|
| Known | Standard normal (z) | .0244 | ±1.96 | ±2.576 |
| Estimated from the 25 scores | t-distribution, 24 degrees of freedom | .034 | ±2.064 | ±2.797 |
The decisions are unchanged here. But the p-value is larger, because estimating the standard deviation adds uncertainty.
Where 1.96 and .05 Come From
The .05 significance level was widely believed to have been fixed by Fisher. Cowles and Davis (1982) examined statistics and probability literature published before Fisher’s (1925) book Statistical Methods for Research Workers.
Fisher gave the first formal statement of the .05 criterion, treating deviations beyond twice the standard deviation as significant. But the idea reached further back.
Earlier conventions were stated in terms of the probable error. This is the deviation exceeded by half of all deviations in a normal distribution.
Simple arithmetic links these conventions to the z-table. Each step cuts off a two-tailed area:
- One probable error: about 0.6745 standard deviations.
- Three probable errors: about 2.02 standard deviations, which cuts off an area of .043.
- Two standard deviations: cuts off an area of .0455.
- 1.96 standard deviations: cuts off exactly .0500.
A critical value such as 1.96 is therefore a decision convention chosen for convenience. A p-value of .049 and one of .051 are not different in kind.
Outlier Screening with Z-Scores
A common rule flags scores with an absolute Z-score above 3 as possible outliers. Treat it as a prompt to investigate, not a verdict. About 2.7 scores in every 1,000 exceed ±3 even in perfectly normal data.
The rule is also blind in small samples. With the sample standard deviation, a sample of n scores cannot produce a Z-score larger than (n − 1) / √n, whatever the data.
- 5 scores: no Z-score can exceed 1.79.
- 10 scores: no Z-score can exceed 2.85.
- 20 scores: no Z-score can exceed 4.25.
Extreme scores also distort the mean and standard deviation. This can hide an outlier’s own Z-score.
Leys et al. (2013) recommend the median and the median absolute deviation instead. A rank-based alternative is the 1.5 × IQR fence used on a box plot.
P-Values Are Easy to Misread
A tail area from a z-table is the probability of data at least this extreme if the null hypothesis, and every other assumption behind the calculation, were true. That is not the probability that the null is true.
According to the American Statistical Association’s statement (Wasserstein & Lazar, 2016), a p-value does not measure:
- Hypothesis probability: the probability that the studied hypothesis is true.
- Chance: the probability that the data were produced by random chance alone.
- Effect size: the size or importance of an effect.
Greenland et al. (2016) list these misreadings among 25 common misinterpretations of p-values, confidence intervals and power.
Significance depends on sample size; effect size does not. In the wellbeing example, a 4.5-point difference gives d = 0.45 whether it is found in 25 participants (p = .0244) or 100 (p ≈ .000007).
A one-point difference (d = 0.1) in 400 participants gives z = 2.00 and p = .0455. That is significant at .05, yet the difference is a tenth of a standard deviation. A small p is not a big effect.
Contemporary Research
How Common Is Non-Normality?
Cain et al. (2017) collected 1,567 univariate and 254 multivariate distributions from authors of articles in Psychological Science and the American Educational Research Journal. Most were not normal.
- Univariate distributions: 74% deviated from normality.
- Multivariate distributions: 68% deviated from normality.
- Simulation: With typical skewness and kurtosis, Type I error rates reached 17% in a t-test and 30% in a factor analysis under some conditions.
There are limits. The sample came from two journals. The simulation tested inferential procedures, not z-table percentiles.
Even so, tail areas depend on the shape of the tails, so skewed data can distort percentile conversions.
An opinion article (Ferr, 2025) adds concrete reasons. Most people in a community sample report few or no symptoms of anxiety or depression. Scores therefore pile up at the bottom of the scale, with a long tail of severe scores.
On such a floor-bound scale, a score of z = −1 may not exist at all. This is argument and examples, not a new analysis.
Modelled Norms Instead of Table Lookups
Conventional test norms rank scores within age bands and convert them to standard scores. Lenhard et al. (2018) proposed a different approach. They modelled raw scores as a continuous function of percentile and age, with no assumption about the shape of the raw data.
They demonstrated it on two psychometric tests, using age norms (N = 3,555) and grade norms (N = 1,400).
A later simulation cross-validated norms on a representative sample of 840,000 cases across 90,000 repetitions (Lenhard & Lenhard, 2021). Modelled norms reached optimal results with much smaller samples. Conventional norming did worse on data fit, age-related errors and missing values in the norm tables.
A simulation is weaker evidence than real clinical data. It still supports the view that rank-based tables are not automatically the safest option.
Do Researchers Misread P-Values?
Badenes-Ribera et al. (2016) surveyed academic psychologists in Italy and Chile online. Of 2,321 invited, 164 answered the p-value questions (a 7.07% response rate). Each respondent saw a result of p = .001 and ticked the statements they judged true.
Inverse-probability errors drew the most endorsement:
- 32.9%: ticked that the null hypothesis had been shown to be false.
- 23.8%: ticked that the probability of the null hypothesis had been determined.
- 61.6%: ticked at least one of five such errors, and methodology specialists were not immune.
Some caution is needed. The sample was a low-response convenience sample. The survey measured what people ticked in a quiz, not how they interpret p-values in their own analyses. It shows that misreadings persist, not how often they change a published conclusion.
Key Takeaways
- Table Layout: Z-tables are cumulative, mean-to-z or tail. Look up z = 1.00 to tell: .8413, .3413 or .1587.
- Reading Entries: The row gives the whole number and first decimal, the column the second decimal. The entry is the area.
- Negative Z: By symmetry, the area left of −z equals the area right of +z. Positive-only tables need subtraction from 1.
- P-Values: A two-tailed p is 2 × (1 − A(|z|)). A p above alpha means we fail to reject the null hypothesis, never accept it.
- Normality: Tail areas are only right for roughly normal data. For skewed data, count percentiles directly.
- Software: Excel’s
NORM.S.DIST(z, TRUE)returns the left-tail area, with no table rounding.
Further Information
Z-Score Table (for positive or negative scores)
Khan Academy video: finding the proportion above a value with a z-score and z-table
Statistics for Psychology Book Download
References
Badenes-Ribera, L., Frias-Navarro, D., Iotti, B., Bonilla-Campos, A., & Longobardi, C. (2016). Misconceptions of the p-value among Chilean and Italian academic psychologists. Frontiers in Psychology, 7, Article 1247. https://doi.org/10.3389/fpsyg.2016.01247
Blanca, M. J., Arnau, J., López-Montiel, D., Bono, R., & Bendayan, R. (2013). Skewness and kurtosis in real data samples. Methodology, 9(2), 78–84. https://doi.org/10.1027/1614-2241/a000057
Cain, M. K., Zhang, Z., & Yuan, K.-H. (2017). Univariate and multivariate skewness and kurtosis for measuring nonnormality: Prevalence, influence and estimation. Behavior Research Methods, 49(5), 1716–1735. https://doi.org/10.3758/s13428-016-0814-1
Cohen, J. (1988). Statistical power analysis for the behavioral sciences (2nd ed.). Lawrence Erlbaum Associates.
Cowles, M., & Davis, C. (1982). On the origins of the .05 level of statistical significance. American Psychologist, 37(5), 553–558. https://doi.org/10.1037/0003-066X.37.5.553
Ferr, H. (2025). The normal distribution is not normal in psychological data: Moving beyond parametric dogma. PLOS Mental Health, 2(8), Article e0000403. https://doi.org/10.1371/journal.pmen.0000403
Fisher, R. A. (1925). Statistical methods for research workers. Oliver and Boyd.
Greenland, S., Senn, S. J., Rothman, K. J., Carlin, J. B., Poole, C., Goodman, S. N., & Altman, D. G. (2016). Statistical tests, P values, confidence intervals, and power: A guide to misinterpretations. European Journal of Epidemiology, 31(4), 337–350. https://doi.org/10.1007/s10654-016-0149-3
Lenhard, A., Lenhard, W., Suggate, S., & Segerer, R. (2018). A continuous solution to the norming problem. Assessment, 25(1), 112–125. https://doi.org/10.1177/1073191116656437
Lenhard, W., & Lenhard, A. (2021). Improvement of norm score quality via regression-based continuous norming. Educational and Psychological Measurement, 81(2), 229–261. https://doi.org/10.1177/0013164420928457
Leys, C., Ley, C., Klein, O., Bernard, P., & Licata, L. (2013). Detecting outliers: Do not use standard deviation around the mean, use absolute deviation around the median. Journal of Experimental Social Psychology, 49(4), 764–766. https://doi.org/10.1016/j.jesp.2013.03.013
Micceri, T. (1989). The unicorn, the normal curve, and other improbable creatures. Psychological Bulletin, 105(1), 156–166. https://doi.org/10.1037/0033-2909.105.1.156
Student. (1908). The probable error of a mean. Biometrika, 6(1), 1–25. https://doi.org/10.2307/2331554
Wasserstein, R. L., & Lazar, N. A. (2016). The ASA statement on p-values: Context, process, and purpose. The American Statistician, 70(2), 129–133. https://doi.org/10.1080/00031305.2016.1154108